In the Classic Macintosh world back in the day it was important to use compression tools to keep files small and also allow you to send Macintosh files through the internet. Floppy disks could only hold a small amount of data so utilizing compression was a way to use the space effectively. I have already made posts on BINHEX and DiskDoubler which where also used for similar purposes. The most popular compression software for Macintosh is Stuffit, which used .SIT and .SEA extensions. One of the other often used tools was called Compact Pro.
Compact Pro, originally know as Compactor, developed by Bill Goodman in the early 1990’s and was quite popular. It was generally faster in its ability to compress and decompress files on the Macintosh. By 1995 the last version was released and by 2002 the software was officially discontinued.
Also, Macintosh files often contain a Resource Fork to go along with the data. Archiving files within a Compact Pro archive could contain both forks along with creation, modification dates and the finder Type/Creator codes. Then an archive could be transferred through the internet or on a non Macintosh file system without loosing these key bits of information.
You can see from the image below, the compression of a PICT file retained the resource fork and finder data with an impressive 60% savings in size.
PICT File within a Compact Pro archive.
Compact Pro could also segment an archive into multiple parts. This was advantageous when needing to copy a larger file on to a set of floppy disks, or for transferring smaller files through the internet and combined later. Segments would be extracted by opening the final segment.
The other nifty feature of Compact Pro is it could create a Self-Extracting Archive. Archiving as an SEA, would compress the file into an archive, but contained within an application which could extract the archive without the use of the the full Compact Pro application. This was used mainly for use on distributed Macintosh file system disks as the application could only be run on a Mac OS system.
The file format is not recognized by PRONOM, and as you can see from the headers above, identification is not easy as there are no magic bytes. Using Unarchiver they identify as Compact Pro.
lsar CP-s01.cpt
CP-s01.cpt: Compact Pro
CP.PICT
The only bytes which seem to be consistent is the first two, but “01 01” is not a signature which is unique to Compact Pro. The Unarchiver uses a more complicated calculation of file size and the CRC for identification, from what I can tell.
The self extracting archive has the same basic structure. I have also noticed on all the archive samples I have, the byte at offset 8 is always “80”. This could be significant.
Another thing to note, when looking at a segmented archive, the first two bytes are in sequence, 0101 for the first, 0102 for the second and so on.
The Digital Preservation Coalition recently released their tech watch report on Preserving Geospatial Data. This adds to reports on CAD, Construction, and others. One of the many areas of difficulties in Digital Preservation is understanding these areas of GIS, CAD, and 3D Modeling software and the file formats which belong to the software titles in this space. Not only are the file formats plentiful but the software is extensive and expensive. Documentation is lacking in understanding the different file formats associated with each software title. These tech watch reports are super useful, but more is needed to enhance the tools we use to better identify, validate, and transform these formats in order to preserve them long term.
I was processing some data sets from a recent collection added to our Scholarly repository and came across some models in the SolidWorks part format. I was surprised to find that this format has been around since 1995 and has yet to be added to the PRONOM registry.
SolidWorks is mechanical design software used for making 3D models which can be made to be individual parts, part of larger assemblies and added to drawings giving engineers access to 3D deisgn on their desktops. Bought by Dassault Systèmes in 1997, they are the makers of the CATIA CAD software. Since 1995 a new version was released almost every year, adding new features and improvements to the format. The original versions made use of the Microsoft OLE object container, but in 2015 the format shifted to a proprietary binary format. Let’s take a look at some samples.
There are three types of SolidWorks file formats, the SolidWork part (sldprt), the assembly (sldasm), and drawing (slddrw). The first versions of SolidWorks used prt, asm, and drw, but quickly added “sld” to avoid confusion with other CAD tools.
We can see this file is a compound (OLE) container file. It’s very useful to have a directory within the container with a version number. With this version number we can use the chart on the file format wiki to see this file was last modified by SolidWorks 97 Plus. The problem comes in when we look at an assembly file and compare.
Almost the same contents, the same version directory. The only difference in content is the file Defaults in the Contents directory. But hard to know if all have the same difference. We will have to look closer at the individual files to hopefully find what sets the different formats apart.
The SolidWorks 2000 format added additional files to the container which can help.
Starting in 2015 the format changed from an OLE container, to a binary file. Here is what the first few bytes look like from a 2015 file and a later 2023 file:
The newer version of the format is much different and is in a proprietary binary format with no specifications, which makes it much more difficult to know which parts of the file can be used for identification. All these new formats have the hex values “00 00 00 04” as bytes 4 through 7. Not very unique for identification. There is another set of bytes which does seem to be consistent for all samples so far, but they vary in their location. The values “34 f6 e6 47 56 e6 47 37 f2” seem to be in every sample. The 10th byte often has the value 34, but in many samples either has 34, B4, 44, 64, or 33. The other formats, SLDASM and SLDDRW also have this pattern which might give us enough to make a good signature. At this time we may not be able to distinguish the different formats, but maybe in the future.
More work is needed to really develop signatures that can identify each format from SolidWorks definitely. My initial assumptions we not completely correct and there are a few exceptions to the patterns I felt were good enough. One unknown is the formats from SolidWorks 95 through 99 and properly identifying them. More samples are needed. I have placed my initial signature and some samples on my GitHub. Please get in tough if you have additional samples or ideas on better identification.
Is there a perfect raster image format? TIFF has been around quite some time and is generally accepted as a preferred preservation format. There have been a few attempts to have a single file contain multiple resolutions with the purpose of providing resolutions for different uses, lower-resolution for web and higher-resolution for print. Even the semi popular JPEG2000 added multiple resolutions to improve the JPEG format. Kodak came up with a few ideas to do this as well. The Kodak PCD, PhotoCD or Image PAC files was one that was used for awhile before it was abandoned. Another was FlashPix.
I briefly mentioned FlashPix on an earlier post about the Microsoft Picture It! format. They are extremely similar. Both. have the same basic structure in a Compound Object format. Some of the FlashPix files generated by Picture It! even have the same identifiers in the CompObj header.
FlashPix was supposed to be the answer to all the problems with storing bitmap image data and how we view the web. Kodak partnered with some big names, Microsoft Corporation, Hewlett-Packard Company and Live Picture, Inc, were among them. Kodak marketed the format and even included it as a native file format to some of its new digital cameras. The format was made official in June of 1996, with a Whitepaper explaining all the benefits and architecture. There was a lot of hype, some even calling it, “Not your Grandma’s format“. Many graphics software started to include support for the new format, including Adobe Photoshop. So what happened, why didn’t the format catch on? Some say it was the size of storing multiple resolutions in one file, others believe it was the complicated Compound Object structure that lead to its demise. Either way, the format had a lot of hype in the late 1990’s, but by the year 2000, it had gone silent and all the websites went away.
FlashPix did have a big impact, and there were many software and hardware devices which were made compatible. There are a few stories left behind of those who scanned all their photos to the FlashPix format only to find a few years later it was unsupported on more modern computers. There was also a few early digital camera’s which could capture directly to the format. Take my Kodak DC260 zoom camera, circa 1998. Changing the Capture Preferences, I can switch between a JPG and FPX.
Using exiftool we can take a look at one of the images from the camera:
exiftool P0004795.FPX
ExifTool Version Number         : 12.73
File Name                       : P0004795.FPX
Directory                       : GitHub/digicam_corpus/Kodak/DC260/DC260_01
File Size                       : 251 kB
File Modification Date/Time     : 2024:01:06 12:54:20-07:00
File Access Date/Time           : 2024:01:06 13:20:46-07:00
File Inode Change Date/Time     : 2024:01:06 13:04:34-07:00
File Permissions                : -rwxrwxrwx
File Type                       : FPX
File Type Extension             : fpx
MIME Type                       : image/vnd.fpx
Code Page                       : Unicode UTF-16, little endian
Data Object ID                  : 13BC5A58-6B90-1B6B-12C9-0800201177F8
Data Object Status              : Exists, Not Purgeable
Creating Transform              : Source Image
Using Transforms                :
Cached Image Height             : 1024
Cached Image Width              : 1536
Comp Obj User Type Len          : 16
Comp Obj User Type              : FlashPix_Object
Visible Outputs                 : 1
Maximum Image Index             : 1
Maximum Transform Index         : 0
Maximum Operation Index         : 0
Thumbnail Clip                  : (Binary data 18480 bytes, use -b option to extract)
Revision Number                 : 1
Create Date                     : 2024:01:06 12:53:29
Modify Date                     : 2024:01:06 12:53:29
Software                        : KODAK DIGITAL SCIENCE DC260
Image Width                     : 1536
Image Height                    : 1024
Subimage Width                  : 1536
Subimage Height                 : 1024
Subimage Color                  : RGB
Subimage Numerical Format       : 8-bit, Unsigned
Decimation Method               : None (Full-sized Image)
JPEG Tables                     : (Binary data 558 bytes, use -b option to extract)
Number Of Resolutions           : 1
Max JPEG Table Index            : 1
Scene Type                      : Original Scene
Software Release                : KODAK DIGITAL SCIENCE DC260
Make                            : Eastman Kodak Company
Camera Model Name               : KODAK DIGITAL SCIENCE DC260
Serial Number                   : 7577
Exposure Time                   : 1/180
F Number                        : 4.7
Exposure Program                : Program AE
Exposure Compensation           : 0
Subject Distance                : 0.520 m
Metering Mode                   : Center-weighted average
Light Source                    : Unknown
Focal Length                    : 24.0 mm
Max Aperture Value              : 4.6
Flash                           : No Flash
Exposure Index                  : 90
Sharpness Approximation         : 0
File Source                     : Digital Camera
Sensing Method                  : One-chip color area
Extension Create Date           : 2024:01:06 12:53:29
Extension Modify Date           : 2024:01:06 12:53:29
Creating Application            : Picoss
Extension Name                  : ijuhsimasa
Extension Persistence           : Always Valid
Extension Description           : Data Object Store 000001
Storage-Stream Pathname         : /Data Object Store 000001
Extension Class ID              : 56616000-C154-11CE-8553-00AA00A1F95B
Used Extension Numbers          : 1
Screen Nail                     : (Binary data 4304 bytes, use -b option to extract)
Subimage Tile Count             : 384
Subimage Tile Width             : 64
Subimage Tile Height            : 64
Num Channels                    : 3
Audio Stream                    : (Binary data 30780 bytes, use -b option to extract)
Aperture                        : 4.7
Image Size                      : 1536x1024
Megapixels                      : 1.6
Shutter Speed                   : 1/180
Preview Image                   : (Binary data 4164 bytes, use -b option to extract)
Focal Length                    : 24.0 mm
The file also does identify in PRONOM:
sf P0004795.FPX
---
siegfried   : 1.11.0
scandate    : 2024-01-17T23:13:59-07:00
signature   : default.sig
created     : 2023-12-17T15:54:41+01:00
identifiers :
  - name    : 'pronom'
    details : 'DROID_SignatureFile_V116.xml; container-signature-20231127.xml'
---
filename : 'P0004795.FPX'
filesize : 250880
modified : 2024-01-06T12:54:20-07:00
errors   :
matches  :
  - ns      : 'pronom'
    id      : 'x-fmt/56'
    format  : 'Kodak FlashPix Image'
    version :
    mime    : 'image/vnd.fpx'
    class   : 'Image (Raster)'
    basis   : 'extension match fpx; container name CompObj with byte match at 53, 36 (signature 2/2)'
    warning :
If you notice, PRONOM has two signatures for the FlashPix format, this image was identified with signature #2. The first signature looks for the string “FlashPix Object”, but the second looks for the CLSID which is unique to each compound object format. FlashPix has the CLSID: {56616700-c154-11ce-8553-00aa00a1f95b}. Looking at many of the other samples I have there is much variation on the use of the string and CLSID.
The images from the Kodak Camera use “FlashPix_Object” string so with the underscore it doesn’t match the first signature, but others I made using Picture It! software used a couple variations. Many don’t use the string at all. Others use a sightly different CLSID in both uppercase and lowercase. We will have to suggest adjustments to the current signature to identify them all.
Looking at the contents of the OLE container we can see some interesting things.
Path = P0004795.FPX
Type = Compound
Physical Size = 250880
Extension = compound
Cluster Size = 512
Sector Size = 64
Size Compressed Name
------------ ------------ ------------------------
188 192 [5]Data Object 000001
272 320 [1]CompObj
388 448 [5]Extension List
144 192 [5]Global Info
Data Object Store 000001
18704 18944 [5]SummaryInformation
816 832 Data Object Store 000001/[5]Image Contents
272 320 Data Object Store 000001/[1]CompObj
988 1024 Data Object Store 000001/[5]Extension List
1624 1664 Data Object Store 000001/[5]Image Info
4332 4608 Data Object Store 000001/[5]Screen Nail_bd0100609719a180
Data Object Store 000001/Resolution 0005
Data Object Store 000001/Audio_bd0100609719a180
1112 1152 Data Object Store 000001/[5]KDC_bd0100609719a180
72 128 Data Object Store 000001/[5]SummaryInformation
108 128 Data Object Store 000001/Audio_bd0100609719a180/[5]Audio Info
30808 31232 Data Object Store 000001/Audio_bd0100609719a180/Audio Stream 000000
6208 6656 Data Object Store 000001/Resolution 0005/Subimage 0000 Header
176378 176640 Data Object Store 000001/Resolution 0005/Subimage 0000 Data
------------ ------------ ------------------------
242414 244480 16 files, 3 folders
The main CompObj is where we find the identification information, but the Data Object Store 000001 directory is where all the image data is stored. In a multiple resolution image we might see additional Resolution directories. You may also notice a mention of an Audio directory. Yes, this image was captured and then audio was recorded with it. Not a video, but an audio clip associated with the image. FlashPix can contain audio streams. This isn’t the first time we have seen this, HP camera’s also have this function which as it turns out is stored in a FlashPix exif extension within a JPEG.
The FlashPix native format may have disappeared, but the format lives on as an extension to Exif data, allowing you to embed audio and other media within a JPEG file. The code for FlashPix was given to ImageMagick and is maintained by them.
Working in preservation and archiving for the last few years has caused me to change a habit most people use everyday. The double-click. I am usually opening a file in a hex editor or control clicking on a file to open it in a different software application than is default. Maybe it’s just me, but having control over opening a file is essential. The thought of double-clicking on a file and the uncertainty of what is actually happening scares me a little.
Of course opening an application executable requires a double-click or a right-click/open process and from there you can open the file of your choosing. Executables are run-able files because they have the required pieces for the operating system and cpu to interpret and well; run. We need executables in order to make sense of the files we preserve. Without something to interpret our the data in our files they are just a bunch of one’s & zero’s.
Take a PDF for example. By itself, it is hard to make sense of the file. You need Acrobat Reader, or any number of other executable software programs to open and render the PDF.
But what if you could take a file and wrap it in an executable so it is all self contained, the file format and an executable in one file! No separate software needed! On the surface this seems like a great idea, which is why a few software companies had this as an option. An early competitor of PDF, Common Ground had the option to embed the DP file into a self contained viewer. Many archive software tools have the ability to make “self-extracting” executables as well. One obvious downside is being unable to execute on a different platform or a later operating system. But at the time they were very convenient.
One software in particular added the option to export a few different formats into a special wrapper making them viewable on any Windows machine.
New Soft Technology Corporation Presto! PageManager is document management software which can view many different file types. The software helps manage document and photo scanning and keep everything organized. The software often came bundled with home consumer scanners, such as the UMAX Astra scanner I bought years ago. With the Windows version of the software you can take one or more photos and “wrap” them into a Presto! Wrapper.
Once exported to a Presto! Wrapper the files within have a portable viewer wrapped up with them. One double-click and Presto!, you can view, rotate, export, and print your images. The wrapper has a your typical .EXE extension and identifies as such.
sf Presto6-s02.EXE
---
siegfried : 1.11.0
scandate : 2024-01-09T23:39:36-07:00
signature : default.sig
created : 2023-12-17T15:54:41+01:00
identifiers :
- name : 'pronom'
details : 'DROID_SignatureFile_V116.xml; container-signature-20231127.xml'
---
filename : 'Presto6-s02.EXE'
filesize : 818301
modified : 2024-01-07T23:48:01-07:00
errors :
matches :
- ns : 'pronom'
id : 'fmt/899'
format : 'Windows Portable Executable'
version : '32 bit'
mime : 'application/vnd.microsoft.portable-executable'
class :
basis : 'extension match exe; byte match at [[0 2] [232 94]]'
hexdump -C Presto6-s02.EXE | head
00000000 4d 5a 90 00 03 00 00 00 04 00 00 00 ff ff 00 00 |MZ..............|
00000010 b8 00 00 00 00 00 00 00 40 00 00 00 00 00 00 00 |........@.......|
00000020 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 |................|
00000030 00 00 00 00 00 00 00 00 00 00 00 00 e8 00 00 00 |................|
00000040 0e 1f ba 0e 00 b4 09 cd 21 b8 01 4c cd 21 54 68 |........!..L.!Th|
00000050 69 73 20 70 72 6f 67 72 61 6d 20 63 61 6e 6e 6f |is program canno|
00000060 74 20 62 65 20 72 75 6e 20 69 6e 20 44 4f 53 20 |t be run in DOS |
00000070 6d 6f 64 65 2e 0d 0d 0a 24 00 00 00 00 00 00 00 |mode....$.......|
00000080 99 72 8f bf dd 13 e1 ec dd 13 e1 ec dd 13 e1 ec |.r..............|
00000090 5e 0f ef ec dc 13 e1 ec b2 0c eb ec d6 13 e1 ec |^...............|
The preservation of executables is, in my opinion, complicated. Running a 32 bit executable on a computer today might not even work. Then we have to get into the license of using the software and wether the license allows us to use it freely in perpetuity. So as much as this is an executable, knowing it is also a wrapper for regular images is important to know as an option for preservation. The files wrapped inside can be exported and preserved as a solution. So what makes this executable unique. Let’s look a little closer.
It is indeed a wrapper, the header looks like any other EXE file, but a little further into the file we can see some specifics to the viewer. In all my samples I can see the string “NewsSoft Viewer“. That might be enough to distinguish it from other executables. See some samples here.
I guess part of the question is wether identifying specific software executables is needed in preservation. Arn’t they all executables and should be treated similar? This isn’t the first type of executables I have seen like this. awhile back I came across another home software which allowed you to make a slideshow, complete with audio and wrap it into an executable to put on a disk so playback was easy for the user and nothing additional was needed. The software is called Family Album Creator, use at your own risk.
Usually in the software world file formats are fairly efficient, the structure is meant to provide a way to store the data of the software being used. There isn’t much need to add additional unnecessary additions. This isn’t always true, but in the early days, disk space was expensive so compression and efficiency ruled. There also wasn’t much need to hide anything or complicate things. That is unless it is intended. This makes me think of two things, Polyglots and Steganography.
Steganography is the art of embedding data within an image. With digital images you can hide another image within the main image by using the most and least significant bits. Fun use of technology, but not something you normally would find in your regular desktop software.
Imagine my surprise when I was researching the Picture It! software and the MIX file format only to discover Microsoft decided to make their own polyglot of sorts for their PNG Plus format which replaced the MIX format, then both obsolete when Digital Image was discontinued in 2007. The PNG Plus format was the native format for the Microsoft Picture It! and Digital Image software often found with the Microsoft Works or Digital Imaging suite of software.
Save Menu from Digital Image Pro
According to the help within Digital Image:
The PNG Plus format uses the standard PNG extension but provides saving of layers and pages within the PNG format. Since the PNG format cannot do this natively, how did Microsoft accomplish this? Well, by throwing an OLE container into the middle of the file of course!
PNG Plus files are your regular PNG format and will identify as such. But they are just a low resolution thumbnail of the full image. Let’s take a look:
exiftool PictureIt7-s02.png
ExifTool Version Number : 12.70
File Name : PictureIt7-s02.png
File Size : 26 kB
File Modification Date/Time : 2023:12:26 22:01:58-07:00
File Access Date/Time : 2024:01:01 12:31:07-07:00
File Inode Change Date/Time : 2023:12:26 22:01:58-07:00
File Permissions : -rwx------
File Type : PNG
File Type Extension : png
MIME Type : image/png
Image Width : 500
Image Height : 333
Bit Depth : 8
Color Type : RGB with Alpha
Compression : Deflate/Inflate
Filter : Adaptive
Interlace : Noninterlaced
SRGB Rendering : Perceptual
Gamma : 2.2
White Point X : 0.3127
White Point Y : 0.329
Red X : 0.64
Red Y : 0.33
Green X : 0.3
Green Y : 0.6
Blue X : 0.15
Blue Y : 0.06
Warning : [minor] Text/EXIF chunk(s) found after PNG IDAT (may be ignored by some readers)
Title : PictureIt7-s02
Image Size : 500x333
Megapixels : 0.167
Looks like there is some additional data after the IDAT chunk.
What what do we have here? Near the end of the file before the IEND chunk is an OLE file with the very recognizable hex values of “D0CF11E0“. Let’s strip out the OLE file and take a look.
Path = PictureIt7-s02-ole
Type = Compound
WARNINGS:
There are data after the end of archive
Physical Size = 8704
Tail Size = 7764
Extension = compound
Cluster Size = 512
Sector Size = 64
Date Time Attr Size Compressed Name
------------------- ----- ------------ ------------ ------------------------
2023-12-26 22:01:58 D.... DataStore
2023-12-26 22:01:58 D.... Text
..... 2560 2560 Text/CONTENTS
..... 86 128 Text/[1]CompObj
..... 96 128 DataStore/3
..... 4 64 DataStore/1
..... 121 128 DataStore/0
..... 57 64 DataStore/2
..... 98 128 DataStore/5
..... 4 64 DataStore/4
..... 1254 1280 DataStore/7
..... 4 64 DataStore/6
..... 4 64 DataStore/8
------------------- ----- ------------ ------------ ------------------------
2023-12-26 22:01:58 4288 4672 11 files, 2 folders
Interesting, I don’t think I have come across a standard format with a container embedded within. I have come across many OLE and ZIP containers which contain other common formats within, but this format is definitely unique. Others have added features in the IDAT chunk, such as a web shell. I am sure there are others out there. The CompObj file found within the Text directory is very similar to the Microsoft Works and Publisher format. Although trying to open the file in Publisher doesn’t work!
PRONOM uses binary and container signatures to identify file formats. Even though this file format contains a valid OLE container, because it is within a regular binary file format, I don’t believe a container signature would work. The difficulty will be to clearly identify this new format without falsely identifying a regular PNG instead. The OLE file format header is not in a consistent location to use a specific offset. Making the string a variable location can causes some undo processing, so lets look to see if there is anything else we can use to make a positive ID.
The PNG file format is based on chunks, you have to have IHDR, then an IDAT and the IEND chunk. If we take a look at a regular PNG file using a libpng tool pngcheck, we see this:
pngcheck -cvt rgb-8.png
File: rgb-8.png (759 bytes)
chunk IHDR at offset 0x0000c, length 13
256 x 256 image, 24-bit RGB, non-interlaced
chunk tEXt at offset 0x00025, length 44, keyword: Copyright
? 2013,2015 John Cunningham Bowler
chunk iTXt at offset 0x0005d, length 116, keyword: Licensing
compressed, language tag = en
no translated keyword, 101 bytes of UTF-8 text
chunk IDAT at offset 0x000dd, length 518
zlib: deflated, 32K window, maximum compression
chunk IEND at offset 0x002ef, length 0
No errors detected in rgb-8.png (5 chunks, 99.6% compression).
The required chunk are there, but a couple extra, the tEXt and iTXt, which are textual metadata you can add. Now lets look at a PNG Plus file:
pngcheck -cvt PictureIt7-s02.png
File: PictureIt7-s02.png (26066 bytes)
chunk IHDR at offset 0x0000c, length 13
500 x 333 image, 32-bit RGB+alpha, non-interlaced
chunk sRGB at offset 0x00025, length 1
rendering intent = perceptual
chunk gAMA at offset 0x00032, length 4: 0.45455
chunk cHRM at offset 0x00042, length 32
White x = 0.3127 y = 0.329, Red x = 0.64 y = 0.33
Green x = 0.3 y = 0.6, Blue x = 0.15 y = 0.06
chunk IDAT at offset 0x0006e, length 9460
zlib: deflated, 32K window, fast compression
chunk cmOD at offset 0x0256e, length 0
Microsoft Picture It private, ancillary, unsafe-to-copy chunk
chunk cpIp at offset 0x0257a, length 16384
Microsoft Picture It private, ancillary, safe-to-copy chunk
chunk iTXt at offset 0x06586, length 24, keyword: Title
uncompressed, no language tag
no translated keyword, 15 bytes of UTF-8 text
chunk tEXt at offset 0x065aa, length 20, keyword: Title
PictureIt7-s02
chunk IEND at offset 0x065ca, length 0
No errors detected in PictureIt7-s02.png (10 chunks, 96.1% compression).
It looks like we have the required chunks and some textual chunks but also a couple chunks which pngcheck describes as private and identify’s them as Microsoft Picture It chunks. The cpIp chunk is the one which contains the OLE container. This is the chunk we need to identify in a signature. The problem is the offset for the cpIp chunk is not the same each time. Here is one from Digital Image 10 Pro.
chunk cpIp at offset 0x737a7, length 245760
Microsoft Picture It private, ancillary, safe-to-copy chunk
Significantly further in the file that the other example. These samples currently identify as PNG 1.2 files. PRONOM fmt/13 so we can use the signature and add to it, but it currently doesn’t look for IDAT only the iTXt chunk, which is probably not optimal. For PNG Plus, lets get the header which includes IHDR, IDAT, then the cpIp chunk then an end of file sequence for IEND. Take a look at my signature and samples, I am curious how many PNG Plus files are out there hidden to the world.
Turns out there is another PNG flavor which has been enhanced to allow for layers and pages. Adobe Fireworks uses a PNG format as their native format. They also use private chunks, but not within an OLE container. They use additional chunks, but before the IDAT chunk:
It’s hard to know which each of the chunks are for and if they are all required for the Fireworks PNG format. From the book on PNG.
In addition to supporting PNG as an output format, Fireworks actually uses PNG as its native file format for day-to-day intermediate saves. This is possible thanks to PNG’s extensible “chunk-based” design, which allows programs to incorporate application-specific data in a well-defined way. Macromedia has embraced this capability, defining at least four custom chunk types that hold various things pertinent to the editor. Unfortunately, one of them (pRVW) violates the PNG naming rules by claiming to be an officially registered, public chunk type, but this was an oversight and should be fixed in version 2.0.
Most everyone has heard of Microsoft Office, the suite of applications used by millions everyday. Less people know about Microsoft Works, which was a lower cost alternative, but was quite popular as a home office suite of applications. One tool which often came with the Works suite was a digital image tool called Picture It!
Picture It! was a photo editing tool first released by Microsoft in 1996 geared to making photo editing easy and affordable.
Picture It! used a wizard type interface which walked you through acquiring an image and adding to it. One of the key features of the software was the ability to “stack” objects like layers. Because of this feature a new file format was used to save this information to disk. Meet the Microsoft Image (Picture) Extension format, commonly known as the MIX file format. It is very similar to the FlashPix image format, which was supposed to be an image file format to solve many delivery issues, but didn’t seem to gain hold despite being created by Kodak, HP, and others. In fact many of the MIX files I found on Microsoft disks are actually FlashPix files.
The MIX extension was also used by another Microsoft program, PhotoDraw, which causes confusion as they were similar, but PhotoDraw has some added features which may not be compatible with Picture It!. Both formats are based on the Microsoft Compound Object (OLE) container, and have a similar structure. Let’s take a look at a MIX file from Picture It! version 1.
7z l PictureIt1-s02.mix
--
Path = PictureIt1-s02.mix
Type = Compound
Physical Size = 48128
Extension = compound
Cluster Size = 512
Sector Size = 64
Date Time Attr Size Compressed Name
------------------- ----- ------------ ------------ ------------------------
..... 328 384 [5]Data Object 000001
..... 396 448 [5]Transform 000004
..... 872 896 [5]Operation 000001
..... 320 320 [1]CompObj
..... 292 320 [5]Global Info
..... 872 896 [5]Operation 000002
..... 144 192 [5]Operation 000003
..... 684 704 [5]Transform 000008
..... 1028 1088 [5]Transform 000009
..... 328 384 [5]Data Object 000009
..... 324 384 [5]Data Object 000005
2023-12-27 11:04:39 D.... Data Object Store 000001
..... 328 384 [5]Data Object 000010
..... 20932 20992 [5]SummaryInformation
..... 200 256 [5]Microsoft Embedding Info
2023-12-27 11:04:39 D.... Data Object Store 000001/Resolution 0001
..... 1400 1408 Data Object Store 000001/[5]Image Contents
..... 230 256 Data Object Store 000001/[1]CompObj
2023-12-27 11:04:39 D.... Data Object Store 000001/Resolution 0000
..... 28 64 Data Object Store 000001/Resolution 0000/Subimage 0000 Data
..... 80 128 Data Object Store 000001/Resolution 0000/Subimage 0000 Header
2023-12-27 11:04:39 D.... Data Object Store 000001/Resolution 0003
2023-12-27 11:04:39 D.... Data Object Store 000001/Resolution 0002
..... 28 64 Data Object Store 000001/Resolution 0002/Subimage 0000 Data
..... 208 256 Data Object Store 000001/Resolution 0002/Subimage 0000 Header
2023-12-27 11:04:39 D.... Data Object Store 000001/Resolution 0005
2023-12-27 11:04:39 D.... Data Object Store 000001/Resolution 0004
..... 28 64 Data Object Store 000001/Resolution 0004/Subimage 0000 Data
..... 1792 1792 Data Object Store 000001/Resolution 0004/Subimage 0000 Header
..... 124 128 Data Object Store 000001/[5]SummaryInformation
..... 28 64 Data Object Store 000001/Resolution 0005/Subimage 0000 Data
..... 6976 7168 Data Object Store 000001/Resolution 0005/Subimage 0000 Header
..... 28 64 Data Object Store 000001/Resolution 0003/Subimage 0000 Data
..... 544 576 Data Object Store 000001/Resolution 0003/Subimage 0000 Header
..... 28 64 Data Object Store 000001/Resolution 0001/Subimage 0000 Data
..... 128 128 Data Object Store 000001/Resolution 0001/Subimage 0000 Header
------------------- ----- ------------ ------------ ------------------------
2023-12-27 11:04:39 38698 39872 29 files, 7 folders
This is a simple MIX file with one line of text, but contains a lot of content inside the OLE container. If I try and use the PRONOM registry to identify the file, I get:
sf PictureIt1-s02.mix
---
siegfried : 1.11.0
scandate : 2023-12-27T11:06:32-07:00
signature : default.sig
created : 2023-12-17T15:54:41+01:00
identifiers :
- name : 'pronom'
details : 'DROID_SignatureFile_V116.xml; container-signature-20231127.xml'
---
filename : 'PictureIt1-s02.mix'
filesize : 48128
modified : 2023-12-27T11:04:40-07:00
errors :
matches :
- ns : 'pronom'
id : 'fmt/111'
format : 'OLE2 Compound Document Format'
version :
mime :
class : 'Text (Structured)'
basis : 'byte match at 0, 30'
warning :
Hmm, we know it is an OLE compound document, but it should identify as a Picture It! file as PRONOM has defined a PUID for the format. fmt/936 has been defined as “Microsoft Picture It! Image File 1”. So I am not sure why this file from version 1 is not identifying correctly. Let’s take a look. The PRONOM container signature for fmt/936 is looking for this:
The container signature is looking into the OLE container for the “CompObj” file (which seems to be required), then looks for the string “Microsoft Picture It! version 1 Picture” starting at the 32nd byte. That is pretty specific. The sample file I am using as an example has the following string of bytes.
Ok, so this sample has a similar string but is missing the “version 1” text. It seems the samples used to created the PRONOM signature was working off samples which included the version 1 in the header of CompObj. Maybe when Microsoft learned they would be making a version 2, they decided a version number should be included going forward. Let’s take a look a file from version 2 to compare:
Ok, so it looks like they did update the version string for version 2. This file also does not identify correctly. A quick look at the wikipedia page for Microsoft Picture It! tells us they continued to release the software until version 10. Is there a different string for each version?
Diving into this and gathering many samples has brought a lot of variants to surface. Let’s see if we can list all the CompObj header variants.
Version 1 samples:
Picture It! Picture'{56616800-C154-11CE-8553-00AA00A1F95B}
Microsoft Picture It! Picture'{56616800-C154-11CE-8553-00AA00A1F95B}
Microsoft Picture It! version 1 Picture'{56616800-C154-11CE-8553-00AA00A1F95B}
Picture It! Collage'{56616800-C154-11CE-8553-00AA00A1F95B}
Version 2 samples:
Microsoft Picture It! version 2 Picture'{2D722850-8C4B-11D0-A96F-00A0C905410D}
Version 3 samples:
Microsoft Picture It! version 3 Picture'{18B8D020-B4FD-11D0-A97E-00A0C905410D}
Version 4 samples:
Microsoft Picture It! version 4 Picture'{18B8D020-B4FD-11D0-A97E-00A0C905410D}
PhotoDraw version 1 samples:
Microsoft PhotoDraw version 1 Picture'{18B8D020-B4FD-11D0-A97E-00A0C905410D}
PhotoDraw version 2 samples:
Microsoft PhotoDraw version 2 Picture'{18B8D021-B4FD-11D0-A97E-00A0C905410D}
FlashPix samples:
FlashPix Object({56616000-C154-11CE-8553-00AA00A1F95B}
FlashPix Object({56616800-C154-11CE-8553-00AA00A1F95B}
Picture It! FlashPix'{56616700-C154-11CE-8553-00AA00A1F95B}
LPI FlashPix'{56616700-c154-11ce-8553-00aa00a1f95b}
FlashPix_Object'{56616700-C154-11CE-8553-00AA00A1F95B}
'{56616700-C154-11CE-8553-00AA00A1F95B}
Picture It!'{56616700-c154-11ce-8553-00aa00a1f95b}
Flashpix Toolkit Application'{56616700-c154-11ce-0000-000000000000}
Ok, there is a lot to discuss here. First of all, it seems MIX was only used in Picture It! until version 5 (2001), then the Picture It! software used a new format, PNG Plus to store the layered stacks. More on that in a future post! Although some later versions seems to be able to open the older MIX format. Version 4 of the MIX format seems to be the last as the 2001 software had only version 4 files on it. Probably safe to say only the 4 versions are needed for identification.
You may notice the additional unique identifier I included in each format. This is called a Class ID for the OLE format, which A LOT of formats use. Each “format” has a unique ID associated with it to help distinguish it from other formats. This Unique ID could possibly be a better solution for identification. It does cross over with the PhotoDraw format, but the FlashPix format seems to have a unique ID. With all the variations in the version 1 strings, the ID remains the same. For version 3 and 4 the ID is the same, which could mean they are interchangeable. It is also the same as PhotoDraw version 1. Not to complicate things.
So it seems in order to get proper identification of these similar formats we need to:
Clean up version 1 identification for fmt/936
Add a signature for 2, 3, and 4
Add a version 2 signature for the PhotoDraw format
Add some additional signature variations for the FlashPix format.
The Class ID’s could be used to distinguish different versions and formats, but many of the ID’s are identical, this could mean they are the same format. But for now we can just add the additional variation strings and it should identify everything for now. The FlashPix format needs more research as there is so many different variations and it’s so close to the MIX format. Take a look at my GitHub submission, maybe you have some additional variations to add?
All I had to go on was it was an Adobe format and the acronym “ACD”. One of the first results that came up in a google search was a post in the Adobe forums with someone asking what to do with some old ACD and ACI files they found on a disc, circa 2000, labeled “Adobe Capture”. The only thing I remember about Adobe Capture was some scanning tools related to Adobe Acrobat, but I didn’t remember coming across any ACD files related to Acrobat.
Initially it wasn’t easy to find more information on this format. Eventually I was able to narrow it down to stand-alone software adobe released called “Adobe Acrobat Capture”. Originally released in 1995 it was eventually discontinued in 2010. The software was marketed under the ePaper name and connected to Acrobat through the creation of a PDF from scanned images. The software was compatible with many scanner models and would process the scanned images, run Optical Character recognition, and export to a searchable PDF. These tools are built into Adobe Acrobat today.
One of the reasons the software was being so elusive is the fact it was sold with a high price tag and required the use of a hardware key, or dongle, in order to process scans. The hardware key also managed the type of license you purchased which may limit the number of pages you are allowed to scan within a certain period of time. So the software is very difficult to run today, if you do happen to find a copy out there in Internet land.
In order to document these file formats for preservation purposes I needed to find some samples. I was excited to find a demonstration CD on the Internet Archive, but unfortunately it contained no examples of the ACD file format.
A little sleuthing on the Wayback Machine helped me find a few user guides and brochures. I was also able to find there was three versions of Adobe Acrobat Capture. In a Product Brochure, you can see a screenshot of the software with a document open with the ACD extension.
If you are OCD like me you might have noticed the window in this screenshot is typical of the older Windows 3.1 or Windows NT system. So this was indeed an older product released by Adobe.
The Adobe Acrobat Capture 3.0 Demonstration CD-ROM from the Internet Archive luckily has a UserGuide PDF on the disc and was able to help me understand the ACD format a little more.
Looks like the ACD format is an intermediate format used by the software to manage the process between scanning and export to PDF. ACD was also defined as an “Acrobat Capture Document” which makes sense. They were also mentioned as being “multipage files in Acrobat Capture Document (ACD)”. The UserGuide also mentioned an ACP format which it referenced as “one-page files are in Acrobat Capture Page (ACP) format.” So more research is needed.
Lets start with Adobe Acrobat Capture 2.0 as I managed to get a few samples from an installer I found. Here is a hexdump of an ACD file and its corresponding ACI file.
The ACD file is unique, PRONOM and even TrID was unaware of the format. But to the keen observer, the ACI format is very recognizable. You may have seen this header before:
Lets take a closer look at an ACI file to see if they are a true TIFF image or if there is any customization to the format.
Looks like a true TIFF image with no special tags or unique properties. They are 1-bit TIFF’s compressed with CCITT RLE. Not sure there would be any need to create a special signature for these ACI files.
Looking closer at the ACD file format, we can see they reference ACI files, so probably safe to assume the ACD file doesn’t contain the full raster data for each image:
From the limited sample set I have access, all the ACD files begin with the same Hex values, “02044747C900”. Along with the common header we can assume there should be at least one ACI file referenced in the first part of the file. Because it is referenced as a filepath, the ACI string would be variable in its offset.
Adobe Acrobat Capture 3.0 turns out to be a different format. But looks familiar………
The ACD has some of the same hex values as the previous version, but with some extra bytes at the beginning and it looks like the ACP is a straight up PDF. But may have some interesting tags, like “CAPT_info”.
The problem we will face when trying to write a signature for this version of ACD is the container signature needs a static file name to reference, and it appears the name of the container is also the name of the ACD file within the container. So every file will be different. I wish there was a way in the PRONOM signature syntax to reference an extension and ignore the filename, but currently there no method to do this. The only thing inside the container which seems to be consistent is the file “FILES.LST”. So lets take a peek inside if it.
hexdump -C FILES.LST | head
00000000  5b 41 43 44 31 5d 0d 0a  49 53 43 4f 4d 50 4f 53  |[ACD1]..ISCOMPOS|
00000010  49 54 45 3d 54 52 55 45  0d 0a 4e 55 4d 46 49 4c  |ITE=TRUE..NUMFIL|
00000020  45 53 3d 31 0d 0a 46 49  4c 45 4e 41 4d 45 31 3d  |ES=1..FILENAME1=|
00000030  43 6f 6e 74 72 61 63 74  2e 61 63 70 0d 0a        |Contract.acp..|
Ok, there seems to be some static information that is unique to the ACD format. I bet the string “[ACD1]” would be sufficient enough to make a solid signature.
This is a good format example of a limited amount of information on the file format used by a well known company which has become obsolete and disappeared. Take a look at my signatures, maybe you have some old ACD files you were unaware of!
In honor of World Digital Preservation Day, I wanted to write a little about format headers, the magic that makes some files more easily identifiable than others.
When it comes to binary file formats, some developers decide to make the format clearly identifiable in a header and others choose to make it ambiguous. Others have a little fun with leaving little clues and references to popular culture.
Like I said some developers make it very obvious what software created the file format and others seem to make things difficult. I understand there is a need to optimize files to keep them from getting bloated and taking up too much space, but many of the size limits from the early days of computing are not an issue anymore. Can’t we be more clear when designing a file format?
Today I want to document one format which was very easy to identify as it spelled out its format very verbosely, but because of the lack of additional documentation makes it very hard to preserve.
Meet the Composite File Management System file format:
Secondly, this format refers to a Universal File Management System or CCmF, which I have found to be the file format for many other extensions, some of which are .goo, .brc, .br3, .br4, .br5, .sfp, .shp, .obp. It doesn’t always have the verbose header, some of them have the following:
Different, but still contains the CCmF identification string. Others have the verbose header, but further down inside the file.
With this format being used with so many well known software titles, I assumed information on the format would we readily available. Alas, not so much. The format even had the name of the creator! “Created by Andrea Pessino, December 1995”. So I reached out. He was on Twitter and I asked about the file format and if there was any documentation available. Twitter (X) has since deleted his responses after he deleted his account, but he told me he wasn’t sure where the documentation might be. One other developer also commented and confirmed they didn’t know where any of the documentation went after they left.
MetaCreations sold Bryce to Corel in 2000, then in 2004 sold it to Daz3D, the current owners. It’s not actively developed anymore being that it was never made into a 64bit application. A blog post explains the format a little more, but concludes it is a secret known only to Daz.
It seems there is a community who would like to see Bryce more open, maybe even open-sourced. This thread discusses the format and the underlying Axiom format used.
The creator Andrea Pessino was able to track down some documentation on the CCmF file structure for me. He explained Axiom was an entire codebase for all MetaTools/Creations applications and plugins. So the CCmF system was more than a file format. The documentation included some information on versioning of a CCmF.
There seems to be a few versions of the CCmF file structure.
CCmFile::kIdentify which corresponds with December 1995 (vers. 5)
CCmFile::kIdentify2 which corresponds with March 1997 (vers. 7)
CCmFile::kIdentify3 which corresponds with October 1998 (vers. 9)
CCmFile::kDfFormat which is a Generic Composite File
The documentation given to me was up to date for 1998, but after Corel purchased Bryce there was some updates made as many material files have the identifier “CCmFile::kIdentify4“.
Bryce 6 & 7 were released by Daz3D and have a different file header. They have the extension .BR6 & .BR7 with the header:
I still need to gather more samples from the various extensions related to this format and the software related to them. More work to do understanding the different uses of the short CCmFile string and the more detailed header and the differences between objects, materials, and models. When I asked Andrea why he used such a verbose file header, his answer was basically, why not!
There really is no “Macintosh Format”, but there sure are a lot of formats you only find on the MacOS. From Resource Forks and iWork formats to unique sound formats, MacOS has them all! Majority of cross-platform software vendors have done a much better job in recent years in making their file formats the same across platforms, but for Apple, they love to make things unique, just for their platform.
Take EMLX for example. Seems to be a trend to add “X” to the end of an older format to breath new life into it. The EML format, or Electronic Mail, has existed for a few decades now, but in 2005 Apple updated their Apple Mail application to use a new format, EMLX.
As far as I know, Apple hasn’t released any documentation on the EMLX format, but many folks out there have asked the question and have been able to “reverse engineer” the format. Lets take a look.
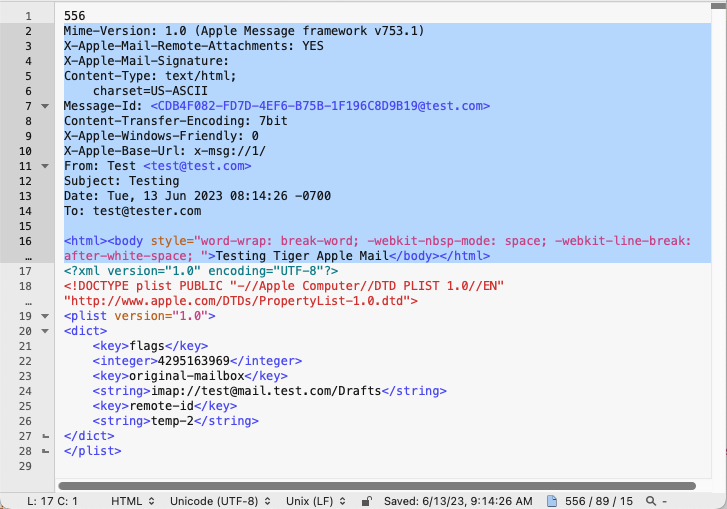
An EMLX file consists of three parts:
bytecount on first line;
email content in MIME format (headers, body, attachments);
The bytecount is a variable number which consists of the total bytes starting from the start of the MIME format, including HTML, to the start of the XML property list. Lets look at a simple EMLX.
The byte count is on line 1 with the MIME email (EML) taking up the 556 bytes, then the XML plist at the end. You may ask, what is a plist? Well, it is another Apple (originally NextStep) invention which is embedded throughout the MacOS operating system. A Plist is usually an XML with keys but can also be in a binary format. The Plist can contain properties of the email within Apple Mail like special color flags, tagged as junk, date received and last reviewed.
If you do happen across an EMLX file or group of them, there are a few tools you can use to convert them to a plain old EML. There are python libraries or many other tools to do the job.
But first we need to be sure of identification beyond the extension. Adding this file format to PRONOM would help in identification for preservation purposes. If ran through PRONOM today we get:
filename : '9.emlx'
filesize : 18582
modified : 2023-10-26T22:16:25-06:00
errors   :
matches  :
  - ns      : 'pronom'
    id      : 'fmt/950'
    format  : 'MIME Email'
    version : '1.0'
    mime    : 'message/rfc822'
    class   : 'Text (Structured)'
    basis   : 'byte match at [[31 17] [599 4] [339 6] [426 6] [90 14]]'
    warning : 'extension mismatch'
Because the format has a EML plain text format within its structure, it is assumed to be an EML file. While technically accurate, Identifying as a unique EMLX format would be beneficial in a preservation system so you can properly assign risk and choose the right tool to parse or migrate.
In looking at the three parts of an EMLX format, we know the EML file is not a good way to show the difference as they are the same structure. The byte count on the first line is variable, so there is no static byte sequence to use for identification. That leaves the Plist section at the end to distinguish the difference.
The PRONOM entry for a Plist looks for the typical XML strings present in most XML files, but then uses the root element “<plist version=”1.0″>” for identification. We could combine the existing EML signature and the Plist signature to identify an EMLX, or just take the existing EML signature and put in a small byte sequence for the closing of the </plist> tag near the EOF? There would be a need for a priority over EML, both would essentially accomplish the same thing.
Take a look at latter idea on my GitHub page and tell me which makes the most sense.
I had access to my first Macintosh computer around 1987. My father brought it home and I spent hours on it playing games and occasionally writing reports for school. The Macintosh Plus computer had one floppy drive and no hard drive. I remember playing the game Orbiter which had two floppy disks and right in the middle of game play it would pause and ask me to insert disk 2, then quickly ask for disk 1 again. The struggle was real. I spent years using many different Macintosh computers and now own more than I wish to admit. I’m preserving them!
The wild world of digital preservation has been a little lacking on the Macintosh side of things as I have come to realize. There still not a great way to manage Resource Forks in many preservation systems and the identification tools are mainly focused on the data bytetreams and not any system specific attributes Macintosh used often.
The PRONOM registry has either referenced early Macintosh specific formats or missed them entirely so I have been slowly working on a few to close that gap.
Interestingly enough, many Microsoft programs initially made their GUI debuts on the early Macintosh before making their way to Windows. Excel is one I am working on, as Version 1 is not identifiable in PRONOM, it was Macintosh only at the time.
Another is PowerPoint, I recently submitted two new signatures to PRONOM.
fmt/1747: Microsoft PowerPoint Presentation v2.x. Full entry added.
fmt/1748: Microsoft PowerPoint Presentation v3.x. Full entry added.
fmt/1866: Microsoft Powerpoint for Macintosh v.2. Full entry added.
fmt/1867: Microsoft Powerpoint for Macintosh v.3. Full entry added.
PowerPoint was initially released in 1987 on the Macintosh platform. It was developed by a company called ForeThought. Version 1.0 on the Macintosh was under this name, until it was bought by Microsoft only three months after being released. The history of PowerPoint can be discovered at Robert Gaskins, one of the original developers, website and book he wrote. The available information provided by Microsoft is only for the OLE format, covering versions 4.0 until 2003.
So, lets take a look at the Powerpoint original file format, before OLE.
   Type/Creator      RF      DF  Date         Filename
f  SLDS/PPNT         0       932 Oct 10 19:10 PowerPoint-v1
Luckily the early PowerPoint files did not have a Resource Fork. The Data Fork, if you haven’t noticed, has an interesting set of hex values at the beginning of the file. 0BADDEED is the first 4 bytes. If we look at a PowerPoint version 2 file from Windows.
The file format is the same, but because of the weird world of endianness, the first few bytes are in reverse order, EDDEAD0B.
Obviously we need to discuss this magic number and the meaning behind “Bad Deed”. This question was asked previously by the digital preservation community. I have a previous blog post about the use of words for the magic number CAFEBEEF as it was used with with JAVA class files and Express Publisher in the 1990’s. BADDEED looks like another clever use of the hex values that formed words. But was there a story behind the words? Joe Carrano asked if this string might be hexspeak. I wanted to know more so I asked some one who might know.
Robert Gaskins was kind enough to chat with me for a bit about the early days of PowerPoint.
I had a theory on the possible meaning behind BADDEED, so I asked him what the feeling was like between Apple and Microsoft at the time. I had heard for years that PowerPoint was originally created for the Macintosh, but Robert informed me:
In fact, PowerPoint was designed first for Microsoft Windows,
and its first spec shows that: “All the screen shots, menus, and
dialogs were set up to look like Microsoft Windows, not like
Macintosh.” (Gaskins, Sweating Bullets, p. 92) You can see that
Of course, we turned out to have been right all along. PowerPoint on
Mac was much loved, but sales remained poor because Mac sales were
so poor. It was only after we shipped on Windows that PowerPoint gained
the dominant market share which has characterized it ever since, and
Windows PPT outsold Mac PPT very quickly. (Gaskins, Sweating Bullets, p. 403)
So my original thought was that there was some bad feelings around this Apple, Microsoft battle which has been the sentiment for quite some time. So when I asked if any of that influenced the use of BADDEED, I was told:
So, far from being disgruntled by expanding PowerPoint to Windows,
that had been our goal all along, and its achievement was the most
important success we had.
I judge that you are fully aware of all that, and that
your question is more, “was there any bad deed signified
by the Mac hex value chosen?” No, it was just the poverty
of choice when you only have six letters.
So there you have it. The use of the hex values 0x0BADDEED, was simply chosen from a limited set of values when looking at words hexadecimal could spell. I guess I should never let the truth get in the way of a good story.
I continued to have a wonderful conversation with Robert and also asked him for some details on the rest of the PowerPoint file format. I was hoping there might be some documentation out there explaining the early format before Microsoft took over. Robert said:
I don’t know of any such documentation apart from the official
Microsoft support files available online. I don’t have any such
information. I know that Dennis Austin deposited some of our
working files at the Computer History Museum (not online):
and it’s likely that some information is there–if nothing
else, it claims to contain a source code listing for PPT 1.0
which would contain the code to read the file format.
So there might be some information in at the Computer History Museum worth looking into.
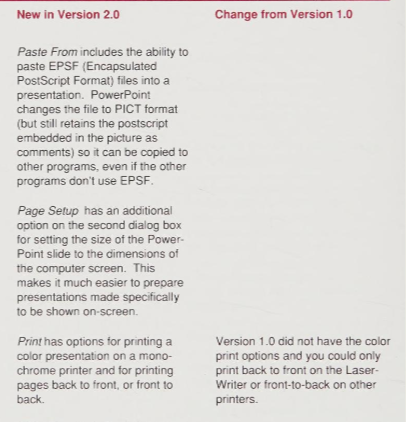
As far as I could tell from the available online information, there is a few differences between Version 1.0 and Version 2.0, the biggest being the fact that 1.0 did not have an option to print in color, amount a few other minor things. Here is a screenshot of a page from the Microsoft PowerPoint 2.0 documentation on archive.org.
I suppose with the signature additions of the Macintosh and Windows versions 2.0 and 3.0 of the PowerPoint file format in PRONOM, that should cover most needs. Currently my PowerPoint 1.0 files identify at 2.0 files, so I may need to have them adjust the PUID to include both versions 1.0 and 2.0 as they are so similar. If I am able to find a difference or get my hands on the original source code I may find a better solution.