Amadeus

Rock me Amadeus! Yes, another music format. Or two? Happy #WDPD2026!

I have found in my research that generally when a format format is needed for software, an extension is chosen based on a recognized pattern that fits with the software’s name or purpose and also something unique to keep confusion limited. Extensions are often three characters long, but over the years with modern operating systems some formats are given four or more characters. So would would think with using more than three characters the extension should be more unique. But there are always exceptions!

For today, I am looking into the extension AMAD. It seems clear this extension belongs to software such as Amadeus. While this is true, there is still some confusion on which Amadeus we are discussing.

Chiptune

The first format to discuss is based on Chiptune technology. This refers to the early intersection of electronic music used in video games and synthesized music. Early arcade games used programmable sound hardware to create complex sound effects and musical compositions. These hardware systems could generate musical waveforms in real time. Later when sound used in video games and other hardware was true recorded music, the need for sound chips was used less, but many still wanted to retain the original simple sounds used earlier.

This led to the AY Amadeus chiptune format. It is a subtype of the AY music file format, which was developed to preserve and reproduce music originally written for the ZX Spectrum’s AY-3-8910 sound chip in the mid 1980’s. The significance of AMAD is that it preserves the original music data and playback requirements rather than simply storing a recording of the resulting sound. You can read more about this format here.

Let’s take a look at some samples.

% hexdump -C ghostbusters.amad | head
00000000 5a 58 41 59 41 4d 41 44 00 00 00 00 00 19 00 00 |ZXAYAMAD........|
00000010 00 00 00 02 00 04 00 38 47 68 6f 73 74 42 75 73 |.......8GhostBus|
00000020 74 65 72 73 00 46 72 61 6e 74 69 73 65 6b 20 46 |ters.Frantisek F|
00000030 75 6b 61 2c 20 6f 72 69 67 2e 20 62 79 20 52 61 |uka, orig. by Ra|
00000040 79 20 50 61 72 6b 65 72 20 4a 72 2e 00 00 f9 b0 |y Parker Jr...??|
00000050 1f 01 24 60 ff 40 00 01 00 01 02 03 b6 f9 90 fb |..$`?@......??.?|
00000060 8e fc 87 ea fd 86 a9 fe 24 30 20 30 1f 30 1e 30 |.?.??.??$0 0.0.0|
00000070 1d 30 27 30 87 b0 fd 23 60 84 14 85 00 82 08 2f |.0'0.??#`....../|
00000080 01 00 05 83 85 08 87 00 fe 86 4e fe 84 09 85 00 |........?.N?....|
00000090 82 08 28 06 83 87 b0 fd 84 1f 85 00 8a 82 20 53 |..(...??...... S|

% hexdump -C popcorn.amad | head
00000000 5a 58 41 59 41 4d 41 44 00 02 00 00 00 14 00 30 |ZXAYAMAD.......0|
00000010 00 00 00 02 00 04 00 4c 50 6f 70 63 6f 72 6e 00 |.......LPopcorn.|
00000020 50 61 74 72 69 6b 20 52 61 6b 2c 20 6f 72 69 67 |Patrik Rak, orig|
00000030 2e 20 62 79 20 4b 69 6e 67 73 6c 65 79 00 53 70 |. by Kingsley.Sp|
00000040 61 63 65 20 43 72 75 73 61 64 65 72 73 2c 20 28 |ace Crusaders, (|
00000050 43 29 20 31 39 39 31 20 53 63 6f 72 70 69 6f 6e |C) 1991 Scorpion|
00000060 00 00 c0 00 1f 01 0a 28 00 00 00 64 00 03 02 01 |..?....(...d....|
00000070 88 c0 06 c0 0b c0 00 00 80 06 c0 86 58 c1 87 51 |.?.?.?....?.X?.Q|
00000080 c1 00 14 82 02 82 04 88 02 81 50 c0 83 88 05 81 |?.........P?....|
00000090 60 c0 88 00 81 60 c0 82 02 88 02 81 50 c0 83 83 |`?...`?.....P?..|

The first four bytes use the hex values “5A 58 41 59” or “ZXAY” in ASCII. Then according to the specifications, the next four bytes indicate these are the “AMAD” file type. Seems pretty straight forward.

The other Amadeus.

Not too long after, there was a clever developer designing software for the early Macintosh to edit sound waves. Martin Hairer is a professor of pure mathematics. He developed the Amadeus software when he was a teenager in the early 1990’s.
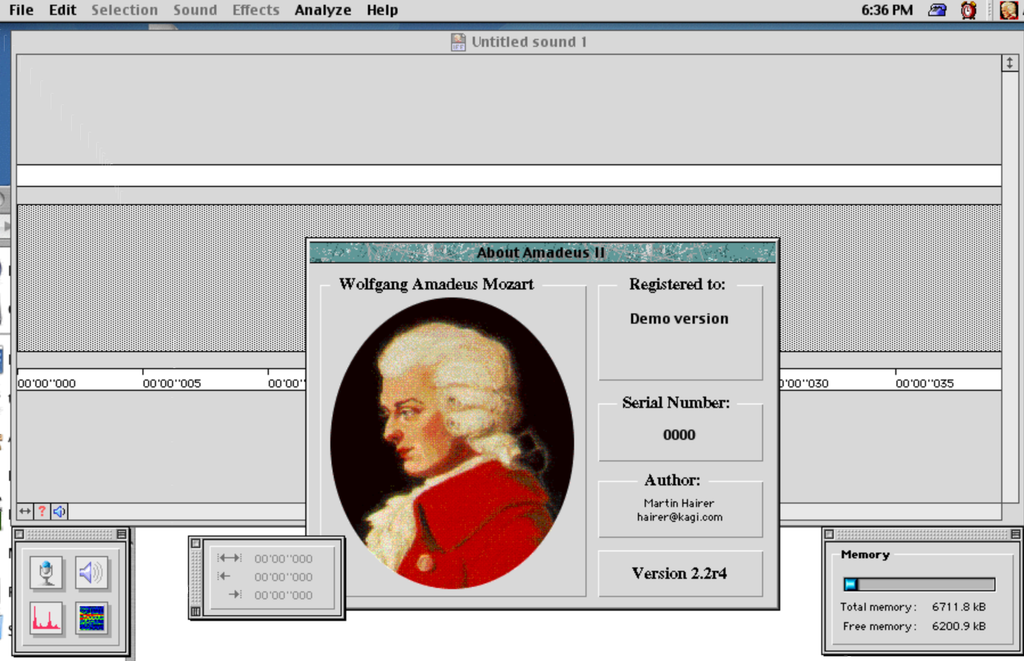
The early version of Amadeus and the later Amadeus II was made for the classic MacOS, but later worked on MacOSX as well. In these early versions, there was no native format for the software. You would simply open or save as one of the popular audio formats of the time. On a Macintosh, this would often be the Audio Interchange File Format (AIFF).

Then around 2007, Martin developed a more modern universal binary version of Amadeus which could run on the intel platform. He called this version Amadeus Pro which added many more features. With this upgrade, also came a native file format to store all the software’s features without restriction. Unfortunately, he also used the AMAD extension.
Let’s take a look at this format as well.

% hexdump -C AP10-s01.amad | head
00000000 61 6d 61 64 00 00 00 00 00 00 04 70 74 72 63 6b |amad.......ptrck|
00000010 00 00 00 00 00 00 03 28 66 6f 72 6d 00 00 00 00 |.......(form....|
00000020 00 00 00 08 47 2c 44 00 00 02 00 02 6f 66 66 73 |....G,D.....offs|
00000030 00 00 00 00 00 00 00 08 00 00 00 00 00 00 00 00 |................|
00000040 65 6e 64 6e 00 00 00 00 00 00 00 04 00 00 00 02 |endn............|
00000050 76 6f 6c 73 00 00 00 00 00 00 01 9c 62 70 6c 69 |vols........bpli|
00000060 73 74 30 30 d4 01 02 03 04 05 06 07 0a 59 24 61 |st00?........Y$a|
00000070 72 63 68 69 76 65 72 58 24 76 65 72 73 69 6f 6e |rchiverX$version|
00000080 54 24 74 6f 70 58 24 6f 62 6a 65 63 74 73 5f 10 |T$topX$objects_.|
00000090 0f 4e 53 4b 65 79 65 64 41 72 63 68 69 76 65 72 |.NSKeyedArchiver|

% hexdump -C AP15-s01.amad | head
00000000 61 6d 61 64 00 00 00 00 00 00 04 e8 76 65 72 73 |amad.......?vers|
00000010 00 00 00 00 00 00 00 02 00 01 74 72 63 6b 00 00 |..........trck..|
00000020 00 00 00 00 03 54 66 6f 72 6d 00 00 00 00 00 00 |.....Tform......|
00000030 00 08 47 2c 44 00 00 02 00 02 6f 66 66 73 00 00 |..G,D.....offs..|
00000040 00 00 00 00 00 08 00 00 00 00 00 00 00 00 65 6e |..............en|
00000050 64 6e 00 00 00 00 00 00 00 04 00 00 00 01 76 6f |dn............vo|
00000060 6c 73 00 00 00 00 00 00 01 c8 62 70 6c 69 73 74 |ls.......?bplist|
00000070 30 30 d4 01 02 03 04 05 08 2e 2f 54 24 74 6f 70 |00?......./T$top|
00000080 58 24 6f 62 6a 65 63 74 73 58 24 76 65 72 73 69 |X$objectsX$versi|
00000090 6f 6e 59 24 61 72 63 68 69 76 65 72 d1 06 07 54 |onY$archiver?..T|

% hexdump -C AP23-s01.amad | head
00000000 61 6d 61 64 00 00 00 00 00 00 07 be 74 72 63 6b |amad.......?trck|
00000010 00 00 00 00 00 00 06 1a 66 6f 72 6d 00 00 00 00 |........form....|
00000020 00 00 00 08 47 2c 44 00 00 02 00 04 6f 66 66 73 |....G,D.....offs|
00000030 00 00 00 00 00 00 00 08 00 00 00 00 00 00 00 00 |................|
00000040 65 6e 64 6e 00 00 00 00 00 00 00 04 00 00 00 01 |endn............|
00000050 65 66 66 73 00 00 00 00 00 00 00 ec 62 70 6c 69 |effs.......?bpli|
00000060 73 74 30 30 d4 01 02 03 04 05 06 14 15 58 24 76 |st00?........X$v|
00000070 65 72 73 69 6f 6e 58 24 6f 62 6a 65 63 74 73 59 |ersionX$objectsY|
00000080 24 61 72 63 68 69 76 65 72 54 24 74 6f 70 12 00 |$archiverT$top..|
00000090 01 86 a0 a3 07 08 0d 55 24 6e 75 6c 6c d2 09 0a |..??...U$null?..|

% hexdump -C AP30-s01.amad | head
00000000 61 6d 61 64 00 00 00 00 00 00 07 fe 74 72 63 6b |amad.......?trck|
00000010 00 00 00 00 00 00 06 5a 66 6f 72 6d 00 00 00 00 |.......Zform....|
00000020 00 00 00 08 47 3b 80 00 00 02 00 04 6f 66 66 73 |....G;......offs|
00000030 00 00 00 00 00 00 00 08 00 00 00 00 00 00 00 00 |................|
00000040 65 6e 64 6e 00 00 00 00 00 00 00 04 00 00 00 01 |endn............|
00000050 65 66 66 73 00 00 00 00 00 00 00 ec 62 70 6c 69 |effs.......?bpli|
00000060 73 74 30 30 d4 01 02 03 04 05 06 07 0a 58 24 76 |st00?........X$v|
00000070 65 72 73 69 6f 6e 59 24 61 72 63 68 69 76 65 72 |ersionY$archiver|
00000080 54 24 74 6f 70 58 24 6f 62 6a 65 63 74 73 12 00 |T$topX$objects..|
00000090 01 86 a0 5f 10 0f 4e 53 4b 65 79 65 64 41 72 63 |..?_..NSKeyedArc|

There is a few things to point out with this format. It is different than the Chiptune format for sure. Should be easy to distiguish between the two, even with them using the same four character extension. The first four bytes are the same as the extension. They are also lowercase so the hex values are different from the Chiptune format, another helpful difference so they two are not confused.

The rest of the format has some similarities with each of the versions, some which could be used to enhance a signature, but the first four bytes should be enough. One of the things things within the format to notice is the bplist00 string. These are binary property lists and are important as they are also a recognized format itself. They contain serialized data, which is a topic I have referenced recently and need to finish a post about that.

So for signatures, I’m thinking:

AY Amadeus chiptune format 5A584159(414D4144|454D554C)

Amadeus Pro Document 616D6164

I am not sure how two completely different developers chose to use the same four character extension for their sound format. I searched for any connection, but couldn’t find one. Seems like a low probability, but Amadeus is a popular historical musical figure, so maybe it wasn’t too hard for these two formats to clash. Let me know what you think. Samples and signature here.
NoteWriter

File formats are part technical and part subject specific. Knowing how a file format is encoded often doesn’t give you much unless you understand the purpose of the software which made it. Take music software, I can dig into the bytes and tell you some interesting details about patterns and metadata, but I really don’t know much of what it means. If there is one subject I was born with zero natural ability, it is music. We have covered formats such as Finale and Sibelius on this blog before, for which I have the same problem. Luckily they had fairly neat understandable byte sequences to work with. Not so much with the next on my list to discuss.

Music software came in the early days of the Macintosh. Finale came in 1988, but so did another score writer, NoteWriter. NoteWriter was written by Dr. Keith Hamel, a Canadian composer, in late 1988. He later wrote:

The main flaw in existing notation software is that the designs of the systems do not adequately encompass the scope and variety of musical notation. … In order to design a music-editing and printing system which could accommodate the entire corpus of existing music notation, the system must permit a variety of notation syntaxes.

NoteWriter was easy to use and fast, according to those who knew how to write music. Around 1996, NoteWriter was replaced with NoteAbilityPro, which was original written for NextStep computers and later for the Macintosh and MacOS X. More on it later.

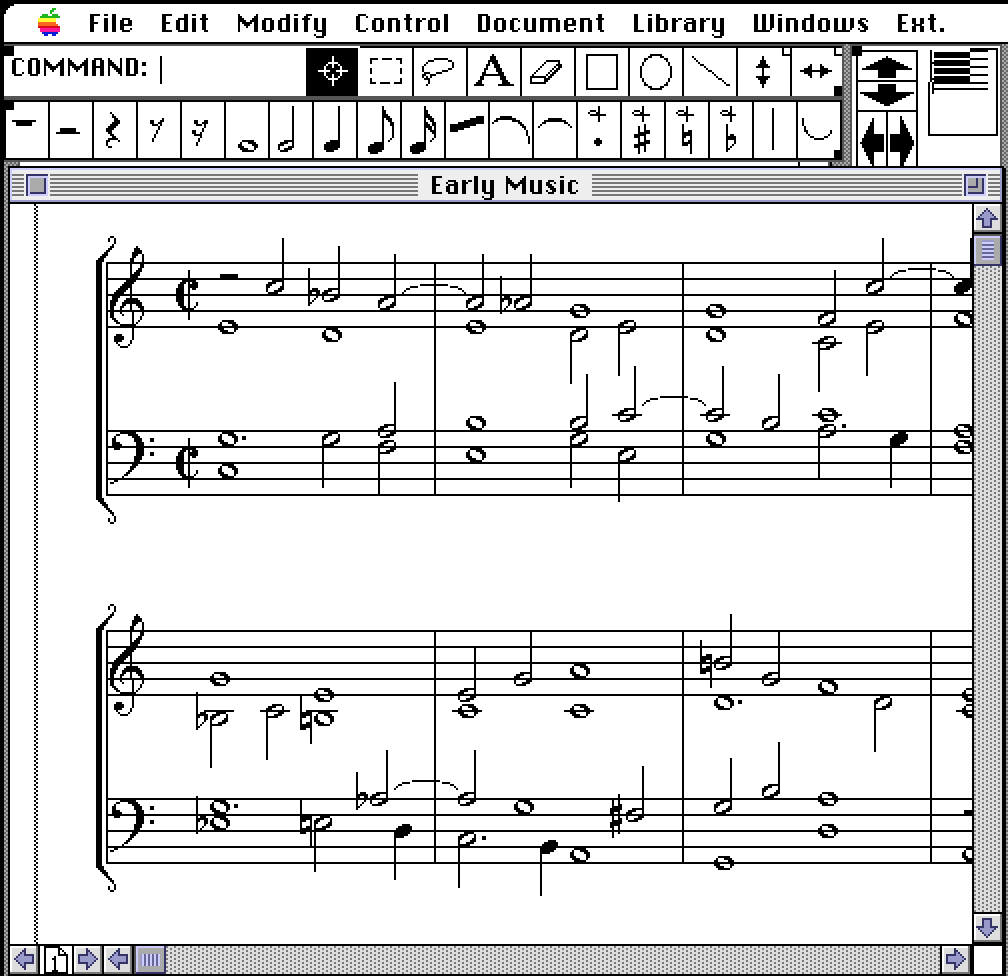
NoteWriter worked a little differently than other score writing software, it used a graphics-oriented method of writing music. Often referred to as the MacPaint or MacDraw of music. This is important because each document produced by the software will also contain the images used to display the notes.

Let’s start by looking at the bytes of a sample file.

% hexdump -C NW269-s01 | head
00000000 00 60 00 c0 01 20 01 80 01 e0 02 40 02 a0 03 00 |.`... .....@....|
00000010 03 60 00 00 00 00 00 00 00 00 00 00 00 00 00 00 |.`..............|
00000020 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 |................|
*
00000050 00 00 00 01 00 01 00 02 00 02 00 03 00 03 00 04 |................|
00000060 00 04 00 05 00 05 00 06 00 06 00 07 00 07 00 08 |................|
00000070 00 08 00 09 00 09 00 00 00 00 00 00 00 00 00 00 |................|
00000080 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 |................|
*
000000a0 00 00 00 58 00 30 02 f8 00 09 03 30 04 20 00 08 |...X.0.....0. ..|

Here is another.

% hexdump -C NoteWriter\ II\ Samples/Early\ Music | head
00000000 00 1d 00 71 00 d5 01 29 01 8d 01 e1 00 00 00 00 |...q.?.)...?....|
00000010 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 |................|
*
00000050 00 00 00 01 00 02 00 03 00 04 00 05 00 06 00 07 |................|
00000060 00 08 00 09 00 0a 00 00 00 00 00 00 00 00 00 00 |................|
00000070 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 |................|
*
000000a0 00 00 00 00 00 30 03 00 00 0a 03 30 04 20 00 08 |.....0.....0. ..|
000000b0 00 17 01 13 00 e6 00 01 00 26 00 2d 00 49 00 01 |.....?...&.-.I..|
000000c0 00 02 00 60 03 c0 00 03 00 00 00 00 00 00 00 00 |...`.?..........|

You may notice the samples don’t have much in the way of human readable strings or a consistent set of bytes at the beginning of the file. This will make identification more difficult. After comparing a few files together, I was unsure what to use as a pattern for a signature, so I decided to try a new approach. I reached out to the author.

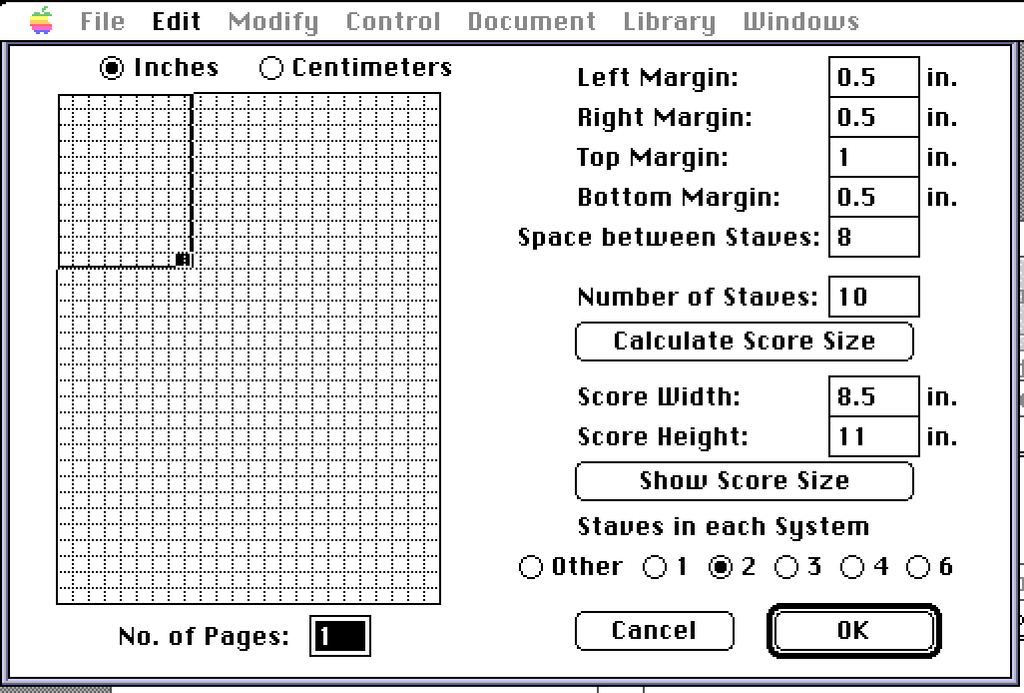
Dr. Keith Hamel was kind enough to help me understand some of the bytes I was looking at. It turns out there is a 366 byte FileData section at the beginning of the file. This is where my lack of music ability becomes a problem. I was introduced to terms like “Staves”, “Flat Key”, “CMajor”, “Staff” starts and ends, etc. I struggle understanding what each of these terms meant on the page, let alone how they might affect a document.

I decided to start making new sample files while changing a few of these parameters. This helped me understand where in the 366 byte header each of these changes reside. Changing the number of pages, for example, changed the last two bytes of the header. Changing the number of “Staves”, which I now know is the basic line of music, changes a 2 byte value at offset 168.

Since the document can have so many different variations, using number of pages can vary, the page size might be different outside the US, margins can change, etc, so I need to find something more simple or static.

In the documentation provided to me, there are a few values which seem to stay constant. One is a dummy value at offset 190, which is always 1, and the MSVersion, which indicates the version of the format. I was told, that there was an early version but it was quickly replaced, so majority if not all the files in the wild should conform to version 2. I also found there is a default indent and where the page “rectangle” starts on the top/left of every document all seem to stay static. I could just use the dummy value and version, but 00010002, seems like it may not be enough to be definitive.

Looking at a sample to see these values:

% hexdump -C NW269-st1 
*
000000a0 00 00 00 58 00 30 02 f8 00 09 03 30 04 20 00 08 |...X.0.?...0. ..|
000000b0 00 17 01 8c 01 9b 00 01 00 26 00 2d 00 49 00 01 |.........&.-.I..|
000000c0 00 02 00 60 00 30 00 03 00 01 00 01 00 01 00 01 |...`.0..........|
000000d0 00 01 00 01 00 01 00 01 00 01 00 00 00 00 00 00 |................|
000000e0 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 |................|
*

So to break it down:

  • Orange = Indent ( 00 30 )
  • Yellow = Outside Rectangle Top/Left ( 00 08 00 17 )
  • Blue = Dummy ( 00 01 )
  • Purple = MSVersion ( 00 02 )

If we were to write this in the PRONOM syntax it would be: 0030{8}00080017{12}00010002 This should make a decent signature, it works for all my samples. 🤞 If you have any Notewriter samples, please let me know if they follow this pattern.

Coming next, NoteAbilityPro and its NextStep roots.

ACE

Without divulging any youthful indiscretions, I recently was going back through some of my personal archives and came across a disc I burned around 2002 with some music stored on it. Normally I would find MP3 files, but in this case the file had a ACE extension. I remembered the format as an alternative to the common RAR or ZIP format often used to compress content for transporting (sharing) around the internet. I did what I normally do when something is compressed and reached for 7zip. But to my surprise, it threw an error.

% 7z l sample.ace 

Scanning the drive for archives:
1 file, 12501419 bytes (12 MiB)

Listing archive: sample.ace


ERROR: sample.ace : Can not open the file as archive

7zip usually can handle most common archives but a part of me remembered there was two versions of WinACE back in the day. Version 1 which was a free version and Version 2 which was for paid users of WinACE. How do I know which version I have is the question I frequently find myself asking. First was to check the PRONOM registry.

% sf sample.ace 
---
siegfried : 1.11.2
scandate : 2025-09-11T09:01:25-06:00
signature : default.sig
created : 2025-03-01T15:28:08+11:00
identifiers :
- name : 'pronom'
details : 'DROID_SignatureFile_V120.xml; container-signature-20240715.xml'
---
filename : 'sample.ace'
filesize : 12501419
modified : 2025-09-11T09:04:36-06:00
errors :
matches :
- ns : 'pronom'
id : 'UNKNOWN'
format :
version :
mime :
class :
basis :
warning : 'no match'

Nope, this format is not known to PRONOM. Lets try another tool.

% file sample.ace 
sample.ace: ACE archive data version 20, from Win/32, version 20 to extract, solid

Ok, so the file tool knows it is a version 2 ACE file and requires version 2 to extract. Good info from a file identification tool. Now lets see what we can find to extract this file on MacOS. The website Winace.com is long gone as this compression tool lost popularity and the final release was over 14 years ago. Looking at the website in the WaybackMachine we can see some downloads available. One being UnACE for Mac OS X, which upon further review, only works for the older PowerPC Mac’s. There is an open source version of unace for Linux, but it only supports version 1, the free version of the format.

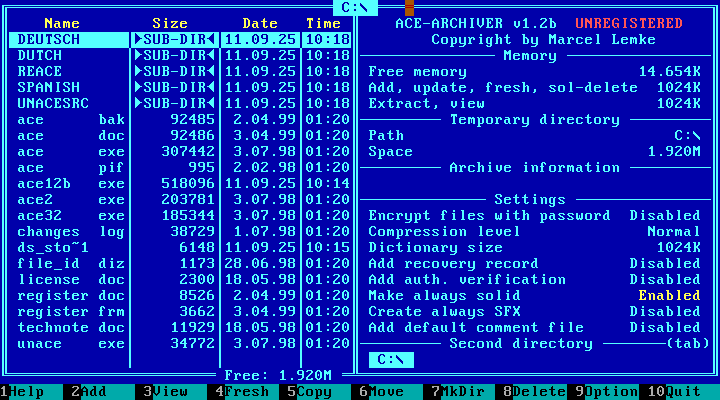
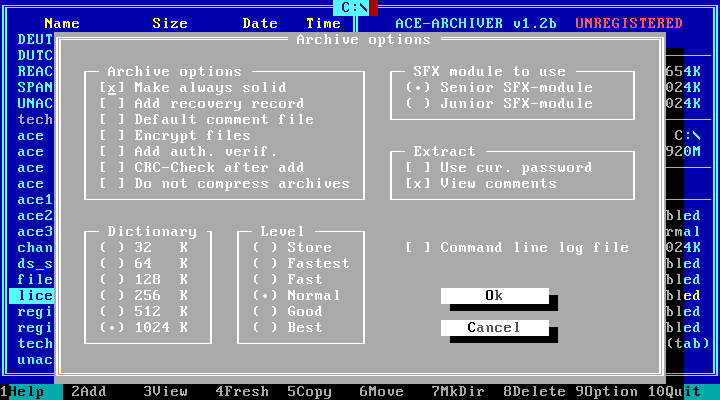
Below is a screenshot of the DOS version of the ACE software. Created by Marcel Lemke.

It might be good to mention that WinRAR used to support the ACE format, but with WinACE support ending years ago and with some new vulnerabilities and folks using it for malware, support was dropped in 2019.

Luckily, I still have my PowerMac G5 lying around waiting for this very situation. After a quick install, unace was able to unarchive my music and I was able to listen to some of my favorite songs from 23 years ago. I still wanted to find a modern solution and later discovered there is a python project which can read and extract bother versions. Acefile is a pure python, no-dependencies implementation of the UnACE format. I had a little issue installing on an older Catalina laptop, but worked well on later MacOS versions. Acefile has a few features that are helpful in not only extracting, but testing and dumping the headers of an ACE file. I did install WinACE in a Windows XP Virtual Machine to make a few samples, here is one of them.

% acefile-unace --test sample.ace 
success test.tif
total 1 tested, 1 ok, 0 failed

The test feature works well to ensure the file is complete and can be extracted, but doesn’t give me much to go on for knowing the version. Lets try dumping the header.

% acefile-unace --header sample.ace 
volume
filename sample.ace
filesize 12501419
headers MAIN:1 FILE:1 RECOVERY:0 others:0
header
hdr_crc 0x4900
hdr_size 44
hdr_type 0x00 MAIN
hdr_flags 0x8100 V20FORMAT|SOLID
magic b'**ACE**'
eversion 20 2.0
cversion 20 2.0

host 0x02 Win32
volume 0
datetime 0x5b2aae37 2025-09-10 21:49:46
reserved1 c8 51 62 e3 5b 80 00 00
advert b''
comment b''
reserved2 b'\x00e\x9c\xb1\xd8\x00\x03\n\x00\x00@\x08\x00test.'
header
hdr_crc 0x3626
hdr_size 39
hdr_type 0x01 FILE32
hdr_flags 0x8001 ADDSIZE|SOLID
packsize 12501328
origsize 25264236
datetime 0x5b2aadcd 2025-09-10 21:46:26
attribs 0x00000080 NORMAL
crc32 0x9290955a
comptype 0x02 blocked
compqual 0x03 normal
params 0x000a
reserved1 0x4000
filename b'test.tif'
comment b''
ntsecurity b''
reserved2 b''

This is very helpful. We can see the output shows the magic bytes, but also the e(xtraction)version and c(creating)version. We can also find this information in the open source unace technical documentation.

       2      HEAD_CRC      CRC16 over block up from HEAD_TYPE
2 HEAD_SIZE size of the block from HEAD_TYPE
up to the last byte of this block

1 HEAD_TYPE archive header type is 0
2 HEAD_FLAGS contains most important information about the
archive

bit discription

0 0 (no ADDSIZE field)
1 presence of a main comment

9 SFX-archive
10 dictionary size limited to 256K
(because of a junior SFX)
11 archive consists of multiple volumes
12 main header contains AV-string
13 recovery record present
14 archive is locked
15 archive is solid

7 ACESIGN fixed string: '**ACE**' serves to find the
archive header

1 VER_EXTRACT version needed to extract archive
1 VER_CREATED version used to create the archive

I think we have enough to go on to create a signature, we just need to see what the 1 byte versions number look like in an actual file.

% hexdump -C sample.ace | head
00000000 00 49 2c 00 00 00 81 2a 2a 41 43 45 2a 2a 14 14 |.I,....**ACE**..|
00000010 02 00 37 ae 2a 5b c8 51 62 e3 5b 80 00 00 00 65 |..7.*[.Qb.[....e|
00000020 9c b1 d8 00 03 0a 00 00 40 08 00 74 65 73 74 2e |........@..test.|
00000030 26 36 27 00 01 01 80 50 c1 be 00 6c 80 81 01 cd |&6'....P...l....|
00000040 ad 2a 5b 80 00 00 00 5a 95 90 92 02 03 0a 00 00 |.*[....Z........|
00000050 40 08 00 74 65 73 74 2e 74 69 66 28 25 a4 89 04 |@..test.tif(%...|
00000060 fa 43 b1 05 49 0c a3 76 8e 16 a9 2c 92 44 34 8c |.C..I..v...,.D4.|
00000070 2c 12 e7 28 67 68 49 69 a7 92 4a 10 07 da 10 16 |,..(ghIi..J.....|
00000080 9c 16 4a 10 07 2b 9c ae 30 a9 50 c4 0a 69 51 a6 |..J..+..0.P..iQ.|
00000090 c9 64 a7 24 09 93 3d 81 26 31 a9 c2 68 32 c1 33 |.d.$..=.&1..h2.3|

As you can see above, we have our magic bytes **ACE** starting at the seventh byte and taking up seven bytes. Then two bytes after it both with the hex value 14. If we convert that hex value to decimal we get “20”. Let’s look at another:

% hexdump -C sample2.ace | head
00000000 61 67 31 00 00 00 90 2a 2a 41 43 45 2a 2a 0a 0c |ag1....**ACE**..|
00000010 02 00 50 7c 31 26 d7 2b c0 48 af 83 ce d9 16 2a |..P|1&.+.H.....*|
00000020 55 4e 52 45 47 49 53 54 45 52 45 44 20 56 45 52 |UNREGISTERED VER|
00000030 53 49 4f 4e 2a 34 5f 24 00 01 01 80 00 00 00 00 |SION*4_$........|
00000040 35 00 00 00 3c 7c 31 26 10 00 00 00 ff ff ff ff |5...<|1&........|
00000050 01 05 0a 00 2a 55 05 00 61 75 64 69 6f 45 72 23 |....*U..audioEr#|
00000060 00 01 01 80 00 00 00 00 35 00 00 00 3c 7c 31 26 |........5...<|1&|
00000070 10 00 00 00 ff ff ff ff 01 05 0a 00 2a 55 04 00 |............*U..|
00000080 42 49 54 53 98 14 24 00 01 01 80 00 00 00 00 35 |BITS..$........5|
00000090 00 00 00 3c 7c 31 26 10 00 00 00 ff ff ff ff 01 |...<|1&.........|

Hmm, now we have two different values. “0A” converts to decimal “10” and “0C” converts to decimal “12”. So we can infer this ACE file was created in version 1.2 and requires at least version 1.0 to extract. Let’s try another:

% hexdump -C sample3.ace | head   
00000000 c0 3f 2c 00 00 00 81 2a 2a 41 43 45 2a 2a 0a 14 |.?,....**ACE**..|
00000010 02 00 dc ad 2a 5b 23 52 89 e0 5b 80 00 00 00 65 |....*[#R..[....e|
00000020 9c b1 d8 00 03 0a 00 00 40 08 00 74 65 73 74 2e |........@..test.|
00000030 92 f3 27 00 01 01 80 54 c3 be 00 6c 80 81 01 cd |..'....T...l....|
00000040 ad 2a 5b 80 00 00 00 5a 95 90 92 01 03 0a 00 00 |.*[....Z........|
00000050 40 08 00 74 65 73 74 2e 74 69 66 28 25 a4 89 04 |@..test.tif(%...|
00000060 fa 43 b1 05 49 0c a3 76 8e 16 a9 2c 92 44 34 8c |.C..I..v...,.D4.|
00000070 2c 12 e7 28 67 68 49 69 a7 92 4a 10 07 da 10 16 |,..(ghIi..J.....|
00000080 9c 16 4a 10 07 2b 9c ae 30 a9 50 c4 0a 69 51 a6 |..J..+..0.P..iQ.|
00000090 c9 64 a7 24 09 93 3d 81 26 31 a9 c2 68 32 c1 33 |.d.$..=.&1..h2.3|

Again we have “0A” which converts to decimal “10” and hex 14, which converts to decimal “20”. So made with version 2.0 of the software, but made compatible with version 1.0 for extraction. One more:

% hexdump -C sample4.ace | head
00000000 8b d6 31 00 00 00 90 2a 2a 41 43 45 2a 2a 0b 0b |..1....**ACE**..|
00000010 02 00 cd b4 3e 26 4a e3 a1 80 32 4b c1 d9 16 2a |....>&J...2K...*|
00000020 55 4e 52 45 47 49 53 54 45 52 45 44 20 56 45 52 |UNREGISTERED VER|
00000030 53 49 4f 4e 2a aa 08 24 00 01 01 00 00 00 00 00 |SION*..$........|
00000040 00 00 00 00 83 b2 3e 26 10 00 00 00 ff ff ff ff |......>&........|
00000050 01 05 0a 00 2a 55 05 00 4d 75 73 69 63 77 73 27 |....*U..Musicws'|
00000060 00 01 01 00 00 00 00 00 00 00 00 00 83 b2 3e 26 |..............>&|
00000070 10 00 00 00 ff ff ff ff 01 05 0a 00 2a 55 08 00 |............*U..|
00000080 52 65 73 6f 75 72 63 65 93 75 25 00 01 01 00 00 |Resource.u%.....|
00000090 00 00 00 00 00 00 00 83 b2 3e 26 10 00 00 00 ff |.........>&.....|

Both extraction and creation version are hex “0B” which converts to decimal “11”. I would have assumed any version 1.0 version could extract anything created with later 1.x versions, but I guess that might not be true. I am not clear on all the versions released, so I am not sure how many versions I should include in a signature. I did look through some of the captured pages on the WayBackMachine and feel the last 1.x version was version 1.32.

When building these signatures, it should be easy to create two signatures based on their extraction version. But should the creation version be a factor? Version 1.0 could look like this:

2A2A4143452A2A(0A|0B|0C|0D)(0A|0B|0C|0D|14)

This accounts for the versions 1.0 through 1.3 for extract version and 1.0 through 2.0 for creation version. Version 2.0 doesn’t seem to indicate minor versions with all 2.0 versions using decimal 14. So a signature could be:

2A2A4143452A2A1414

Both would start from offset 7 from the beginning of the file. Is there a better solution?

I will warn you, there are a couple of ACE formats out there which you may come across. One being an image/texture format for Microsoft Train Simulator. That might be for another day. There is another use of the ACE archive which is worth discussing. The Comic Book Archive file with the extension CBA will use the ACE archive for storing a series of images used in some Comic Book Readers. They are indeed ACE archive files, only having the different extension and a specific purpose. Maybe adding the CBA extension to the signature would be sufficient?

I am sure there are some other properties, seen above, of the ACE format we could discuss, encryption, the differences between Solid and SFX, and dictionary headers, but I think for now, identification of the format and the main version difference is sufficient. For now, check out my Github page for my signature proposal and a few samples I made.

More Student Writing Center

Most of what you will find on this blog is file format identification. I see this as the first step in a longer process of preservation and ultimately access. Hopefully the analysis of some file formats can help make better decisions when needing to render the file in an emulator or migrate to another format. I don’t spend much time trying to parse the files I look at to understand the actual content, just enough to properly identify and differentiate between important versions of the format.

One area I sometimes touch on, but often skim over is encryption. Many file formats are binary, meaning they use a sequence of bytes to encode data which is more efficient than human readable text and is often compressed. The bytes used to store data is designed by the developer of the software, they can encode the data however they choose, which is often unreadable by anyone else and is proprietary. A file can also be further encrypted by a password to limit use, even with the right software.

I recently had one of the numerous fans of this blog reach out and ask about the post I made on the software Student Writing Center. They had a bunch of journal files from their youth and couldn’t find a way to read these older files. I offered my help as I still have the software and a nice emulator to run the old software.

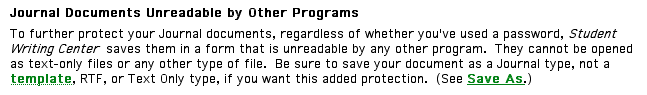
As I was going through and converting the journal entries into a PDF. I came across a few which asked for a password to open. You can see below the explanation from the help menu confirms the file format is a proprietary format only readable by their software and the password feature is to further protect the content.

Finding a few of the journal documents password protected was frustrating at first. I was converting some documents that are over 26 years years old, I doubted the password would be remembered. When I asked, they gave me a couple passwords to try, but nothing worked. But I don’t give up that easily!

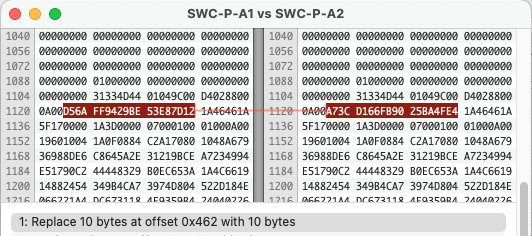
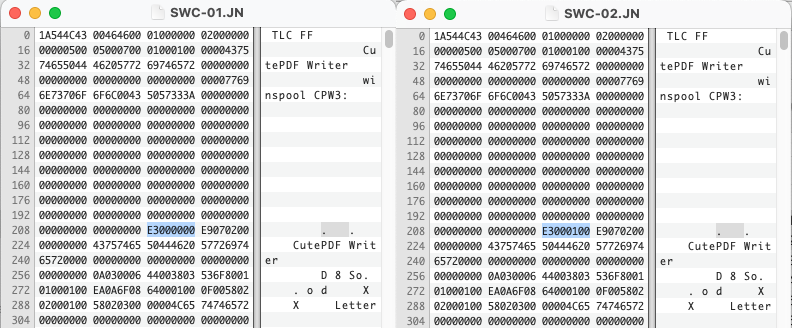
My first thought was to take all the text from the other journal entries and make a dictionary and then use it to try and brute-force the password. There are some great tools to do this like hashcat. With tools like this, you need to retrieve a hash of the password. This is an encrypted sequence of the password stored in the file. So the first step was to find where the password was stored in the file. Since I have the software and can make new password protected files using a password of my choice this proved a simple task. Create two identical files, add a password to each but different. Then compare the two files in a hex editor to find the difference.

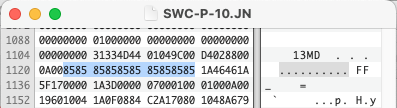
There it is. The password field in the software only let me put in 10 characters and these 10 bytes lit up when I ran a difference between the two files. I went to check the files given to me which also had password protection and found they also had a similar pattern. In fact I noticed from a few checks that the passwords I used also had a pattern in the file.

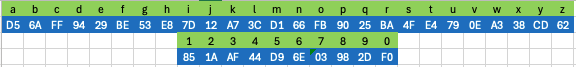
For this file I used the number “1” ten times. In that same location it repeated the same byte value”85″, 10 times. After a couple more tests I could see this wasn’t an algorithm I need to crack, but a simple replacement. I created a few more files using all the letters in the alphabet and all the numbers and came up with a substitution cypher.

Obviously the passwords used in the documents I was trying to open didn’t all use the full 10 characters, but the password was always preceded by the values “00” and had the values “1A46461A” after the password. The byte prior to the “00” indicates the length of the password. From there I just needed to decode the bytes between those two offsets.

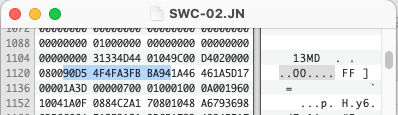
So for this file with an 8 byte sequence “90D54F4FA3FBBA94” decodes to: password. How cool is that? To make things even easier, the passwords used in Student Writing Center are not case sensitive. There are additional values for symbols. You can see the entire substitution list here.

One other thing related to identification. Would it be important to identify a password protected file differently than a regular file? At offset 0xDA there seems to be a indicator that the file is password protected. “00” if not “01” if protected.

What do you think? Should this property be identified as a separate file format from a regular file or is this property something that should be gathered using additional tools that can gather additional properties from a file like this?

Speaking of additional tools. There is a pretty cool project called the Import library for legacy Mac documents or libmwaw which claims to have support for Student Center Writing documents and a lot more. It indeed does, but not the journal format, only the main letter format. I bet it wouldn’t take much to add the journal format to the library, something I will look into.

Microstation

I recently was able to image a few Bernoulli Disks for a collection using a SCSI device I have found quite useful. The disks had been sitting around for quite some time waiting for the right tools and resources to extract the contents. I mentioned the accomplishment to a few coworkers and one asked me if I would extract the contents from their old disk they used for school back in the 1990’s. They had spent a whopping $99 at the local bookstore for a disk which held a total of 150MB. Not GB’s like we are used to now, but megabytes. I have some camera’s which takes RAW photos larger than then would fit on one disk. Once I had the data extracted from their disk, I took a look at the contents. There was a few file formats on the disk I was unfamiliar with. A quick scan with DROID revealed some matches and a few problems.

Turns out the data were files written by an old version of Bentley Microstation. The files dated from late 1995 and the disk was formatted for FAT16 which leans more to being used in a DOS system, but could have been used with the newly released Windows 95. The Bentley Microstation 95 software wasn’t released until November of 1995, so my guess is these Microstation files where created with the Microstation version 5 for DOS.

disktype HD6_imaged-004.hda 

Regular file, size 144.0 MiB (150998016 bytes)
No type and creator code
DOS/MBR partition map
Partition 4: 144.0 MiB (150978560 bytes, 294880 sectors from 32, bootable)
Type 0x06 (FAT16)
FAT16 file system (hints score 5 of 5)
Volume size 143.8 MiB (150810624 bytes, 36819 clusters of 4 KiB)
Volume name "ode 009 - I"

PRONOM has a few entries for the Microstation software:

PUIDFormat NameFormat NameExtension
x-fmt/346Microstation CAD Drawing95DGN
fmt/502Bentley V8 DGNDGN
fmt/1626MicroStation Symbology Resource FileRSC
fmt/1549Bentley Microstation Hidden Line FileHLN
fmt/1358MicroStation Base FileBSE
fmt/1183MicroStation Material PalettePAL
fmt/1177MicroStation Material LibraryMAT

The files found on this old Bernoulli disk gave varied results in identification. Most of the DGN files give me this multiple Identifications in DROID.

A little digging and we can learn a bit about the major formats. Integraph and Bentley used a Binary version of their drawing format, DGN, from versions 2 until 7, spanning 1987 to 2001, with the release of version 8, they made a major change to the format. Version 8 use the Microsoft OLE2 container to enhance the format allowing it to hold multiple drawings and more information about the model. With this change, the format became proprietary. Sure, they started an OpenDGN program to make the format more compatible with other systems, but required you to sign an NDA in order to get a copy of the format specifications. You had to request access and sign an NDA, which doesn’t sound “open” to me. You can read another file format researchers thoughts on this on her blog.

So I know many of these files are not Version 8 of the DGN format as they are not OLE2 containers, but the other issue is that x-fmt/346 for the Microstation CAD drawing 95 is an outline record. It has no signature. So DROID is guessing based on extension only. We need to dig deeper.

I noticed than many of the DGN files in my sample set also identified as a “Microstation Hidden Line File”, but instead of a HLN extension, they use DGN.

sf samp15.dgn 

filename : 'samp15.dgn'
filesize : 359424
modified : 1998-09-01T12:31:52-06:00
errors :
matches :
- ns : 'pronom'
id : 'fmt/1549'
format : 'Bentley Microstation Hidden Line File'
version :
mime :
class : 'Model'
basis : 'byte match at [[0 3] [359422 2]]'
warning : 'extension mismatch'
hexdump -C samp15.dgn | head
00000000 08 09 fe 02 01 08 00 00 00 00 00 00 00 00 00 00 |................|
00000010 00 00 00 00 00 00 00 00 00 00 00 00 20 00 c8 45 |............ ..E|
00000020 00 00 00 00 00 00 00 00 40 06 0c 00 01 05 dc a0 |........@.......|
00000030 ff ff ff ff ff ff ff ff b5 8b 9f 63 b9 88 85 a7 |...........c....|
00000040 00 00 00 00 19 00 b4 86 13 00 fe be 00 00 00 00 |................|
00000050 80 40 00 00 00 00 00 00 00 00 00 00 00 00 00 00 |.@..............|
00000060 00 00 00 00 00 00 00 00 80 40 00 00 00 00 00 00 |.........@......|

hexdump -C samp7.dgn | head
00000000 c8 09 fe 02 01 08 00 00 00 00 00 00 00 00 00 00 |................|
00000010 00 00 00 00 00 00 00 00 00 00 00 00 00 04 7a 45 |..............zE|
00000020 00 00 00 00 00 00 00 00 e8 03 0a 00 01 05 fc b0 |................|
00000030 ff ff ff ff ff ff ff ff 0d 00 9d b5 0c 00 74 93 |..............t.|
00000040 ff ff a6 fd 09 00 40 11 05 00 50 aa 00 00 e5 f8 |......@...P.....|
00000050 80 40 00 00 00 00 00 00 00 00 00 00 00 00 00 00 |.@..............|
00000060 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 |................|

Looking at a couple files in the same sample set, some use the header “08 09 fe 02 01 08 00 00” while another uses “c8 09 fe 02 01 08 00 00”. This is why samp15.dgn identifies as an HLN files as the signature matches, while samp7.dgn uses “C8” instead of “08” making it not identify as an HLN file. What is the difference and what is an HLN file?

First let’s define an HLN file. The name of the format is “Hidden Line File”, although most references refer to it as a “Visible Edges File“. Confusing, but the definition is: “a 2D or 3D DGN file that contains the edges visible in a 3D view (that is, with those edges that would be hidden, removed).”

Looking at a couple HLN files, we can see the format is the same as DGN files:

hexdump -C test-2d.hln | head
00000000 08 09 fe 02 08 01 00 00 00 00 00 00 00 00 00 00 |................|
00000010 00 00 00 00 00 00 00 00 00 00 00 00 20 00 7a 45 |............ .zE|
00000020 00 00 00 00 00 00 00 00 e8 03 0a 00 00 05 fc b2 |................|
00000030 ff ff ff ff ff ff ff ff ff ff 5b f5 ff ff fe f9 |..........[.....|
00000040 00 00 00 00 01 00 d3 cb 01 00 36 2a 00 00 e8 03 |..........6*....|
00000050 80 40 00 00 00 00 00 00 00 00 00 00 00 00 00 00 |.@..............|
00000060 00 00 00 00 00 00 00 00 80 40 00 00 00 00 00 00 |.........@......|
00000070 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 |................|

hexdump -C test-3d.hln | head
00000000 c8 09 fe 02 00 00 00 00 00 00 00 00 00 00 00 00 |................|
00000010 00 00 00 00 00 00 00 00 00 00 00 00 20 00 7a 45 |............ .zE|
00000020 00 00 00 00 00 00 00 00 e8 03 0a 00 00 05 fc b2 |................|
00000030 ff ff ff ff ff ff ff ff ff ff 5b f5 ff ff fe f9 |..........[.....|
00000040 ff ff 0c fe 01 00 d3 cb 01 00 36 2a 00 00 e8 03 |..........6*....|
00000050 80 40 00 00 00 00 00 00 00 00 00 00 00 00 00 00 |.@..............|
00000060 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 |................|
00000070 80 40 00 00 00 00 00 00 00 00 00 00 00 00 00 00 |.@..............|

Same difference between the two previous files. These two files also explain the difference between the “08” and the “c8” values. Microstation uses the first to indicate it is a 2D file and the latter to indicate a 3D file. The DGN format has been documented in libdgn and this distinction is referenced.

This presents a problem with the current PRONOM identification.

filename : 'MS95-2D.dgn'
filesize : 12288
modified : 2025-06-05T21:13:52-06:00
errors :
matches :
- ns : 'pronom'
id : 'fmt/1549'
format : 'Bentley Microstation Hidden Line File'
version :
mime :
class : 'Model'
basis : 'byte match at [[0 3] [12286 2]]'
warning : 'extension mismatch'

filename : 'MS95-3D.dgn'
filesize : 12800
modified : 2025-06-05T21:14:00-06:00
errors :
matches :
- ns : 'pronom'
id : 'x-fmt/346'
format : 'Microstation CAD Drawing'
version : '95'
mime :
class :
basis : 'extension match dgn'
warning : 'match on extension only'

The 2D files mis-identify as Hidden Line Files and the 3D files are identified through extension only. We learned from a previous test that Hidden Line Files can be both 2D and 3D and are the same format as DGN, so a separate identification PUID is unnecessary, but the x-fmt/346 identification doesn’t have a signatures, so a few things need to change.

The other issue is a Hidden Line File is also available in version 8+.

filename : 'Microstationv8-s01.hln'
filesize : 7168
modified : 2025-06-05T19:48:09-06:00
errors :
matches :
- ns : 'pronom'
id : 'fmt/502'
format : 'Bentley V8 DGN'
version :
mime :
class : 'Image (Vector)'
basis : 'container name Dgn~H with name only'
warning : 'extension mismatch'

They also identify as Bentley V8 DGN files, but with an extension mismatch. This should be easy to remedy with the addition of the extension HLN to the signature. The container signature seems to work well, no need to change anything.

My suggestions to fix these issues would be:

  • Depreciate x-fmt/346
  • Change name of fmt/1549 from “Bentley Microstation Hidden Line File” to “Microstation CAD Drawing” and use the version 2-7 to distinguish from v8
  • Change the signature for fmt/1549 from “0809FE” to “(08|C8)09FE02” no EOF of “FFFF”

The other option would be to make fmt/1549 the 2D drawing format and x-fmt/346 could be used for the 3D drawing format. What do you think?

I have uploaded a few samples to my GitHub page. Curious if your examples of DGN files match what I am seeing. There are a few other related formats that will need to be explored, but this should help for now.

SCP

If you have been following previous posts about Floppy disk flux captures, you may have read about the HFE or A2R flux image formats. Both very useful in the preservation, archiving and emulation of old software and games stored on decaying and copy-protected floppy disks. I also built a Fluxengine which has come in handy more than once. It captures flux data in its own FLUX format. At work I also have access to a Kryoflux board which captures in separate RAW tracks.

Today we are looking at the SCP format. I recently purchased a Greaseweazle for personal use and the main format used while capturing raw flux data is SCP. It works a little better on my older MacBook Pro than the fluxengine and I wanted to have another option for capturing flux data. So far it has worked really well. Of course I wanted to know everything I could about the SCP format so the first thing I did was run Siegfried against a file.

filename : 'unknown.scp'
filesize : 47017278
modified : 2025-06-14T19:09:58-06:00
errors :
matches :
- ns : 'pronom'
id : 'UNKNOWN'
format :
version :
mime :
class :
basis :
warning : 'no match'
- ns : 'wikidata'
id : 'Q29000565'
format : 'SuperCard Pro dump'
URI : 'http://www.wikidata.org/entity/Q29000565'
permalink : 'https://www.wikidata.org/w/index.php?oldid=1866792367&title=Q29000565'
mime : 'application/octet-stream'
basis : 'extension match scp; byte match at 0, 3 (Wikidata reference is empty)'

Looks like Wikidata has a signature pattern, but PRONOM does not. Lets take a look and see how difficult it might be.

hexdump -C unknown.scp | head
00000000 53 43 50 00 80 03 00 a3 23 00 00 00 d2 0f 26 99 |SCP.....#.....&.|
00000010 b0 02 00 00 14 43 04 00 c6 96 08 00 64 78 0d 00 |.....C......dx..|
00000020 ea bb 12 00 de 37 16 00 a2 b3 19 00 26 68 1e 00 |.....7......&h..|
00000030 42 b7 23 00 2a 33 27 00 c8 ae 2a 00 a8 54 2f 00 |B.#.*3'...*..T/.|
00000040 fc 94 34 00 e2 10 38 00 a8 8c 3b 00 98 68 40 00 |..4...8...;..h@.|
00000050 1c b6 45 00 14 32 49 00 cc ad 4c 00 9e 9b 51 00 |..E..2I...L...Q.|
00000060 0e d3 56 00 de 4e 5a 00 74 ca 5d 00 be 7b 62 00 |..V..NZ.t.]..{b.|
00000070 b4 b3 67 00 a8 2f 6b 00 68 ab 6e 00 50 88 73 00 |..g../k.h.n.P.s.|
00000080 0c ce 78 00 02 4a 7c 00 ae c5 7f 00 96 bd 84 00 |..x..J|.........|
00000090 8a 2d 8a 00 8a a9 8d 00 56 25 91 00 b6 a3 95 00 |.-......V%......|

Well, probably not hard at all. I love easy well understood headers. But only three bytes can have issues, lets look a little closer at the published specification. Before we dive into the spec, it might be good to note a few things. The SCP image format was developed for another hobby board. A Supercard Pro, is a custom board to connect a floppy drive through USB to software which can also capture flux data and help interpret the data to a image format which can be used to write back to a floppy or used in an emulator. The software is Windows only so those on Linux or MacOS can’t use it, but since the specification was made public, many other boards and tools can read and write to the format. Even though it is open, I worry about preserving the spec. When you try and ensure it is saved in the WayBackMachine you get this fun page.

This sorry page is usually found when the owner of a URL has asked specifically for their domain to be excluded from the web archive. This worries me as I have found many specifications have been lost to time. I would love to know why the owner has chosen to do this, but it is available now, so lets dive in. The versions appear to have started in 2014, but the page is copyright 2012, so I assume the format was created around this time. It was last updated in February of 2024, so is pretty up-to-date. One important update was made in 2021:

v2.3 - 06/03/21

* Added additional FLAG bit (bit 7) to identify a 3rd party flux creator. PLEASE
SET THIS BIT IF YOU ARE A 3RD PARTY DEVELOPER USING THE SCP FORMAT!

This update to version 2.3 added a bit to indicate the 3rd party flux creator. This means a board like the Greaseweazle will indicate its software as the creator instead of a SCP created by SuperCard Pro.

The header of an SCP file is comprised of a few bytes, not just the ASCII “SCP”.

All offsets are the start of the file (byte 0) unless otherwise stated.  The .scp image
consists of a disk definition header, the track data header offset table, and the flux
data for each track (preceeded by Track Data Header). The image file format is described
below:

BYTES 0x00-0x02 contains the ASCII of "SCP" as the first 3 bytes. If this is not found,
then the file is not ours.

With Byte 0x03, we will see the version of the software which created the SCP. In my sample, created by my Greaseweazle, did not add a number here, only “00”. Byte 0x04 is the disk type, there is some set definitions in the spec for this byte. My test sample uses “80”, but not sure what that represents. Bytes 5-7 are used for other disk information, but byte 8 is where we find the flags which include a bit for flux creator. My sample has the value “23”, but since we are looking at the individual bit level, the value will be a combination of all the bits in the flag area. The individual bits are, “00100011”, so since the seventh bit is set, then the SCP was created by 3rd party which is correct.

So the only reliable static data in the header will be those first 3 bytes. There is some bytes later in the file which should be static. That is the start of the Tracks, which include a Track Data Header. We can see from the spec, the last byte in the main header is 0x2AF, which makes the main header 687 bytes long. Starting on the 688 byte, or 0x2B0 is the ASCII string TRK. Adding these 3 bytes should make for a nice signature.

000002b0  54 52 4b 00 a9 86 65 00  5e b5 00 00 28 00 00 00  |TRK...e.^...(...|
000002c0 ab 86 65 00 60 b5 00 00 e4 6a 01 00 56 87 65 00 |..e.`....j..V.e.|
000002d0 60 b5 00 00 a4 d5 02 00 00 39 00 7e 00 7c 00 ce |`........9.~.|..|
000002e0 00 c7 00 c7 00 cd 00 7e 00 7c 00 eb 00 4f 00 60 |.......~.|...O.`|
000002f0 00 39 00 77 00 cd 00 7c 00 7f 00 ce 00 c7 00 c6 |.9.w...|........|
00000300 00 ce 00 7a 00 80 00 cd 00 c8 00 c6 00 ce 00 7b |...z...........{|

We could use the TRK string for identification, but looking further into the spec, we can also see the SCP format may contain a footer.

; ------------------------------------------------------------------
; EXTENSION FOOTER FORMAT
; ------------------------------------------------------------------
;
; 0000 DRIVE MANUFACTURER STRING OFFSET - 4 bytes
; 0004 DRIVE MODEL STRING OFFSET - 4 bytes
; 0008 DRIVE SERIAL NUMBER STRING OFFSET - 4 bytes
; 000C CREATOR STRING OFFSET - 4 bytes
; 0010 APPLICATION NAME STRING OFFSET - 4 bytes
; 0014 COMMENTS STRING OFFSET - 4 bytes
; 0018 IMAGE CREATION TIMESTAMP - 8 bytes
; 0020 IMAGE MODIFICATION TIMESTAMP - 8 bytes
; 0028 APPLICATION VERSION (nibbles major/minor) - 1 byte
; 0029 SCP HARDWARE VERSION (nibbles major/minor) - 1 byte
; 002A SCP FIRMWARE VERSION (nibbles major/minor) - 1 byte
; 002B IMAGE FORMAT REVISION (nibbles major/minor) - 1 byte
; 002C 'FPCS' (ASCII CHARS) - 4 bytes

Here is the tail of my sample file, you can see it contains the ASCII characters listed here for the last four bytes. It also contains an application string, indicating the Greaseweazle software used to create the file. All every helpful information. We can also see on the 5th to last byte the value “24”, this indicates the file format version being used. Version 2.4 being used in this file but we know 2.5 is the latest. I wonder if it would be valuable to have separate identification for version 1 and 2 of the format? Could also consider assigning version 2.3 and 2.4 as unique as they will have the additional 3rd party information.

hexdump -C unknown.scp | tail
02cd6cb0 00 85 00 5a 00 39 00 90 00 75 00 8e 00 42 00 3c |...Z.9...u...B.<|
02cd6cc0 00 78 00 2e 00 42 00 3a 00 47 00 78 00 42 00 46 |.x...B.:.G.x.B.F|
02cd6cd0 00 33 00 52 00 29 00 3a 00 55 00 5d 00 5b 00 54 |.3.R.).:.U.].[.T|
02cd6ce0 00 35 00 e0 00 48 00 91 00 75 00 3a 00 36 00 33 |.5...H...u.:.6.3|
02cd6cf0 00 55 02 03 01 d3 00 33 00 58 11 00 47 72 65 61 |.U.....3.X..Grea|
02cd6d00 73 65 77 65 61 7a 6c 65 20 31 2e 32 32 00 00 00 |seweazle 1.22...|
02cd6d10 00 00 00 00 00 00 00 00 00 00 00 00 00 00 fa 6c |...............l|
02cd6d20 cd 02 00 00 00 00 66 1d 4e 68 00 00 00 00 66 1d |......f.Nh....f.|
02cd6d30 4e 68 00 00 00 00 00 00 00 24 46 50 43 53 |Nh.......$FPCS|

So maybe we don’t need the TRK header in our signature, just the first 3 bytes and last 4 bytes. I believe this should allow for proper identification, while avoiding false positives.

I have a proposal for a PRONOM signature and a sample file on my Github page. Other samples files can be found all over the interwebs, with many on archive.org.

miniDVD

Let’s talk about the DVD format for a minute. Specifically the miniDVD media format.

DVD’s are indeed versatile, as the name implies. You can find files on them written in many different filesystems, including digital video. DVD-Video is a video format which replaced VHS tapes as a main source of home movie entertainment. Eventually the public could afford to record their own video onto these discs and enjoy them for years. With the popularity of high definition video, DVD’s are not as popular as they once were, but still provide a decent experience.

I often see the DVD-Video format in archives I work with and we use tools to “RIP” the already digital data from the disc into a new format. I use the term “RIP”, to indicate we are not digitizing the format as it already contains digital data. DVD-Video is a standard that is used on most discs and looks something like this:

tree /Volumes/VIDEO_ESSENTIALS 
/Volumes/VIDEO_ESSENTIALS
├── AUDIO_TS
└── VIDEO_TS
├── VIDEO_TS.BUP
├── VIDEO_TS.IFO
├── VIDEO_TS.VOB
├── VTS_01_0.BUP
├── VTS_01_0.IFO
├── VTS_01_0.VOB
├── VTS_01_1.VOB
├── VTS_01_2.VOB
├── VTS_01_3.VOB
├── VTS_01_4.VOB
├── VTS_02_0.BUP
├── VTS_02_0.IFO
├── VTS_02_0.VOB
└── VTS_02_1.VOB

3 directories, 14 files

There is usually a AUDIO_TS and a VIDEO_TS folder. The Video folder is full of video files, but the Audio folder is always empty. Apparently is was going to be used for an audio format that was abandoned, so it remains empty. Often times I will see this folder absent on non-commercial discs.

An issue that has come up many times is often I find folks copy the folder structure from the disc to preserve the video as they would with any digital file. This can be an issue as the structure was meant for software and hardware used to access the DVD-Video format. The files by themselves can often not provide the same experience, especially if the disc contains any sort of encryption, then the files are useless. This is a complex, multi-part format and should remain together in this structure or migrated to a new format, such as an MKV for preservation.

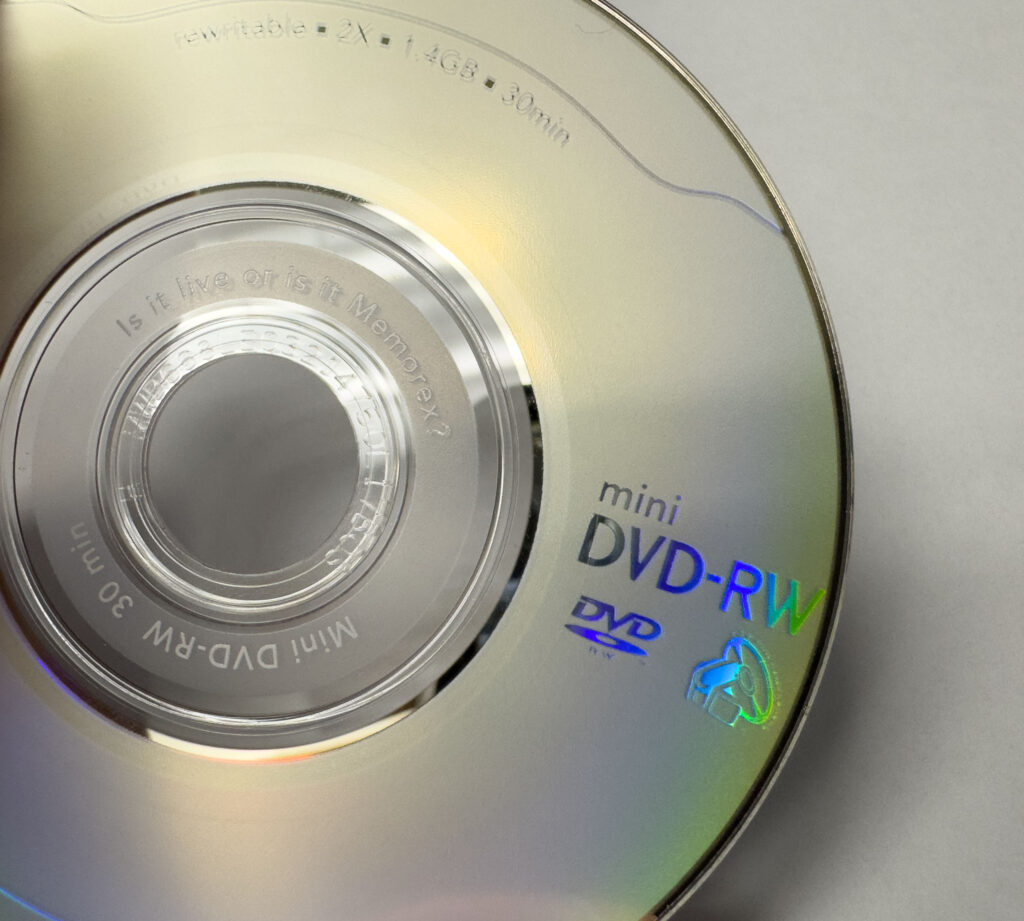
Enter the miniDVD. It is a smaller version of the standard CD/DVD optical disc size. It was very popular as a recording medium for some digital video camera’s. Much like the Sony miniDVD handycam I own. You can pop a blank disc into the camera and it prepares it for you, which takes a couple minutes, then gives you 20 minutes of recording in high quality and up to 60 minutes with a lower quality. The discs can hold up to 1.4GB and will have the same structure as its big brother.

tree /Volumes/2025_05_23_07H36M_PM 
/Volumes/2025_05_23_07H36M_PM
└── VIDEO_TS
├── VIDEO_TS.BUP
├── VIDEO_TS.IFO
├── VIDEO_TS.VOB
├── VTS_01_0.BUP
├── VTS_01_0.IFO
└── VTS_01_1.VOB

2 directories, 6 files

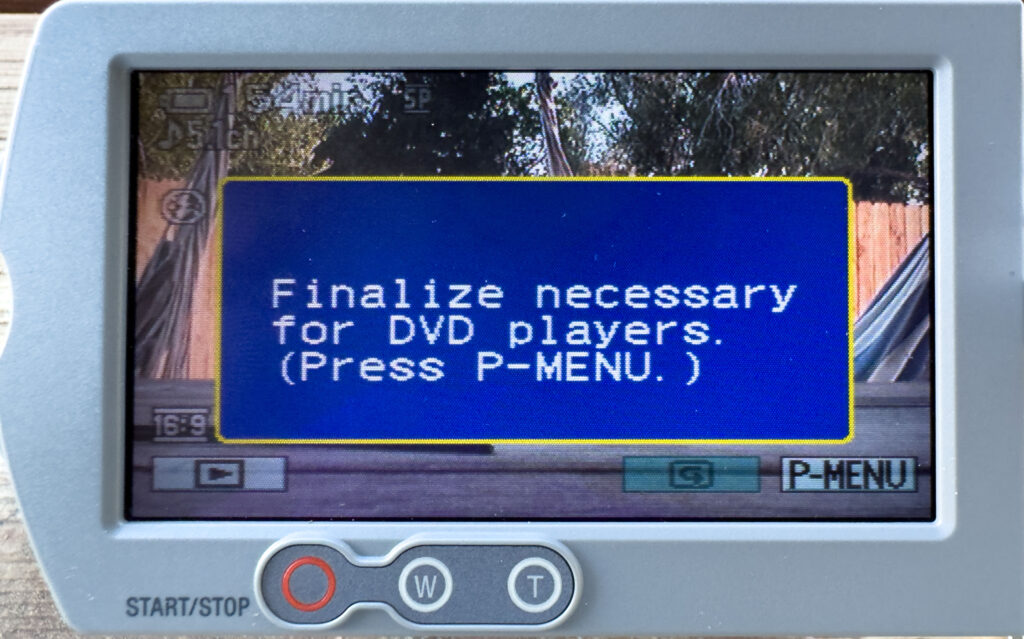
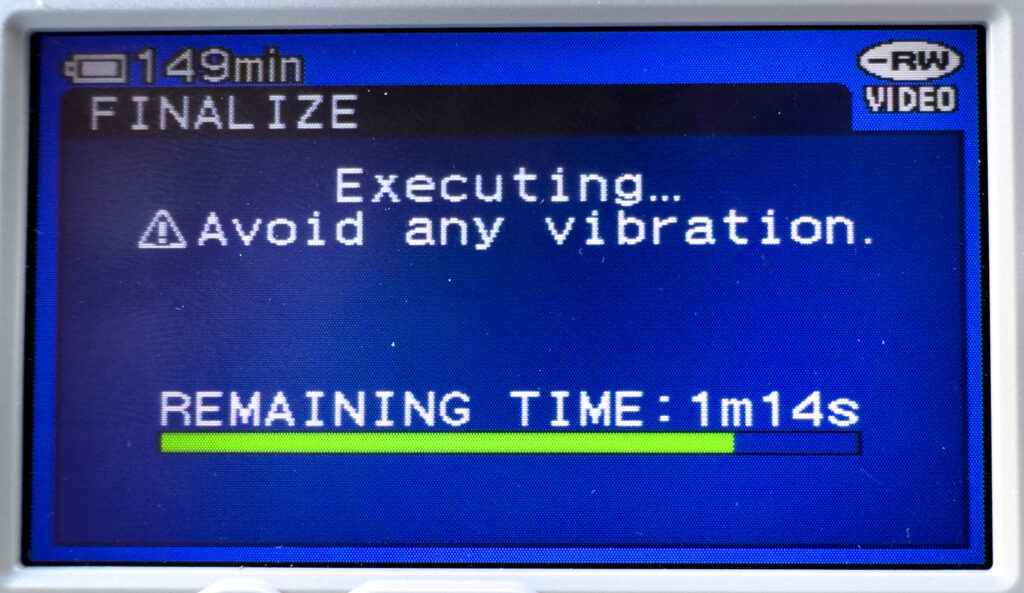
It is missing the AUDIO_TS folder, which is fine, but here is the catch. In order for the disc to be readable by another device, it has to be finalized!

Finalizing is an action which has to happen to any optical disc to “close” out the disc. This process adds important directory and file system data so computers and DVD Players can read the disc properly. Many camera’s like mine and other DVD Recorders require this step when you are finished recording. Unfortunately, it’s an extra step which can take a few minutes, so its is often forgotten. I have had many optical discs come to me over the years because they show up as blank or uninitialized when read on a computer. I fear many people have put them aside or thrown them away as blank, not knowing they have data on them. Luckily with most burnable discs, you can often see the difference from a blank disc and a burned disc from the underside, writable surface.

The filesystem used on most DVD-Video discs is called UDF, Universal Disk Format. It is often combined on hybrid discs with ISO-9660 and HFS for compatibility, but can be the only filesystem as well. According to the specifications, a UDF formatted disc should have a Volume recognition sequence to identify as a UDF disk. On a finalized disc I can find this sequence, but on an un-finalized disc, it is missing. This makes sense as the the disc is often seen as unformatted. A tool I use to explore a disc like this is with ISOBuster.

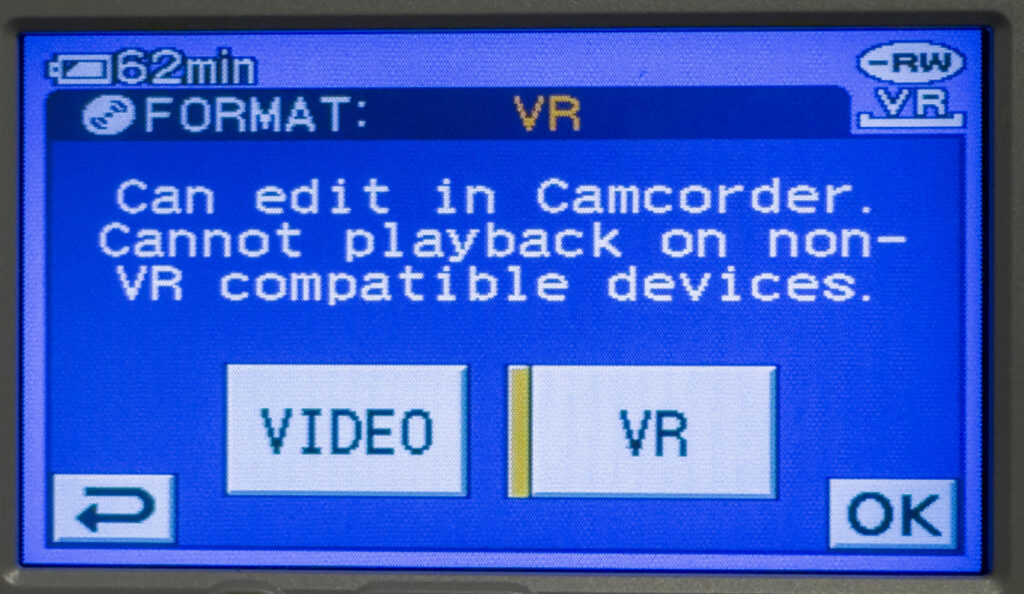
Another interesting feature of my Sony Handycam is the option to choose what type of disc you would like to prepare when you insert a blank disc. I get the option to choose Video or VR mode. Video is your normal DVD-Video format, but VR Mode is something a little different.

tree /Volumes/2025_05_23_08H29M_PM 
/Volumes/2025_05_23_08H29M_PM
└── DVD_RTAV
├── VR_MANGR.BUP
├── VR_MANGR.IFO
└── VR_MOVIE.VRO

2 directories, 3 files

Instead of your expected VIDEO_TS folder, we see a DVD_RTAV folder with some different files inside. No this is a Virtual Reality mode, like I originally thought, the VR simply stands for Video Recording and is a standard. It is meant to allow for easier editing of the video format, but is not compatible with your standard DVD Player. The VRO format used is pretty cool, it is a container format, MPEG-PS, for both audio and video, also containing both 4:3 and 16:9 aspect ratios, unlike a VOB where the aspect ratio is set.

hexdump -C /Volumes/2025_05_23_08H29M_PM/DVD_RTAV/VR_MOVIE.VRO | head
00000000 00 00 01 ba 44 00 04 00 04 01 01 89 c3 f8 00 00 |....D...........|
00000010 01 bb 00 12 80 c4 e1 04 e1 7f b9 e0 e8 b8 c0 20 |............... |
00000020 bd e0 3a bf e0 02 00 00 01 bf 07 d4 50 00 00 00 |..:.........P...|
00000030 00 4d e3 00 00 00 00 00 ff ff ff ff ff 00 00 00 |.M..............|
00000040 00 00 00 00 00 00 00 00 53 4f 4e 59 5f 4d 4f 42 |........SONY_MOB|
00000050 49 4c 45 20 20 20 20 20 20 20 20 20 20 20 20 20 |ILE |
00000060 20 20 20 20 20 20 20 20 41 52 49 5f 44 41 54 41 | ARI_DATA|
00000070 01 02 ff ff 53 4f 4e 59 00 44 43 52 2d 44 56 44 |....SONY.DCR-DVD|
00000080 30 30 34 47 00 01 55 53 52 54 59 50 45 31 4c 4b |004G..USRTYPE1LK|
00000090 00 10 01 00 00 00 00 00 00 00 00 00 00 00 00 00 |................|

The VRO file does identify as a MPEG Program stream (x-fmt/386), but does contain a little extra information. My trusty copy of the book DVD Demystified has a bunch more info on this format if you are interested, you can find a copy here. The VRO format is an MPEG PS so identification is covered, but the current PRONOM signature doesn’t like the VRO extension. The BUP & IFO files on the disc are not identified. This is because the PRONOM signature, which covers both of these formats, is looking for the ASCII string “DVDVIDEO-VTS” or “DVDVIDEO-VMG”. It won’t find either of those strings as this is not the DVD-Video standard. instead it should look for the string “DVD_RTR_VMG” found in these files.

hexdump -C /Volumes/2025_05_23_08H29M_PM/DVD_RTAV/VR_MANGR.IFO | head
00000000 44 56 44 5f 52 54 52 5f 56 4d 47 30 00 00 7f ff |DVD_RTR_VMG0....|
00000010 00 00 00 00 00 00 00 00 00 00 00 00 00 00 02 07 |................|
00000020 00 11 00 00 00 00 00 00 00 00 00 00 00 00 00 00 |................|
00000030 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 |................|
00000040 1e 5c 03 11 ff ff ff ff ff ff ff ff ff ff ff ff |.\..............|
00000050 ff ff ff ff ff ff ff ff ff ff ff ff ff ff ff ff |................|
00000060 ff ff 4d 41 59 20 32 33 20 32 30 32 35 20 20 20 |..MAY 23 2025 |
00000070 38 3a 32 39 50 4d 00 00 00 00 00 00 00 00 00 00 |8:29PM..........|
00000080 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 |................|

I will probably suggest this addition to PRONOM for identification, but if you need to work with this format, you can use tools like: https://www.pixelbeat.org/programs/dvd-vr

LUTS

If you are looking for LUTs, you’re in luck. There is a website for sharing your FreshLUTs. Even though they are fresh, they are probably not as exciting as one might think.

LUTs are short for Look-Up Tables, which doesn’t sound as exciting as you were probably hoping. They are a pretty interesting process for dealing with color in high end Image and Video processing applications. Often called 3D Look-up Tables, they are used for color grading, an essential step in film production and restoration to map from one color space to another. LUTs are not to be confused with ICC profiles which aim for color accuracy, while LUTs are looking for more color quality and aesthetics.

There are a lot of LUT formats out there, it seems. In looking into this format, I have found dozens of others to investigate, but today lets look at the four available as an export from Photoshop.

Above you can see a simple screenshot for the export of different formats from Adobe Photoshop. Adobe is one of the biggest developer and supporter of the formats used in LUTs, but there are many other graphics tools which create and support LUTs. In this Photoshop export we can see four formats included in the export. Lets take a look at each of these.

ICC Profiles are well documented and available for identification in PRONOM.

filename : 'LUTs-Export-s01.icc'
filesize : 197024
modified : 2025-02-25T09:37:24-07:00
errors :
matches :
- ns : 'pronom'
id : 'fmt/1975'
format : 'ICC Profile'
version : '2'
mime : 'application/vnd.iccprofile'
class : 'Dataset'
basis : 'extension match icc; byte match at 8, 32'

But the other three are plain text files and still identify as such. Let us start with the CUBE format.

filename : 'LUTs-Export-s01.cube'
filesize : 884963
modified : 2025-02-25T09:37:24-07:00
errors :
matches :
- ns : 'pronom'
id : 'x-fmt/111'
format : 'Plain Text File'
version :
mime : 'text/plain'
class :
basis : 'text match ASCII'
warning : 'match on text only; extension mismatch'

cat LUTs-Export-s01.cube
#Created by: Adobe Photoshop Export Color Lookup Plugin
#Copyright: (C) Copyright 2025 ObsoleteThor
TITLE "LUT-export-s01"

#LUT size
LUT_3D_SIZE 32

#data domain
DOMAIN_MIN 0.0 0.0 0.0
DOMAIN_MAX 1.0 1.0 1.0

#LUT data points
0.000000 0.000000 0.000000

The CUBE format was first developed by IRIDAS in 2003 as a answer to ensure interoperability with other software. Adobe acquired IRIDAS in 2011 in a effort to be a leader in the color grading and enhancement market. They have published the CUBE specifications for version 1.0 in 2013.

A Cube file is a text file that defines a look-up table in the Cube format.
The Cube look-up tables store RGB values.
Advantages of the Cube format include:
  • The Cube format can describe look-up tables for a wide range of purposes, from simple gamma adjustments for display output to complex HDR image processing.
  • The format is well suited for professional digital cinema applications and for both normal range and High-Dynamic Range image processing.
  • As Cube files are text files, they are easily edited or reviewed using a text editor.
  • A Cube file can include three 1-dimensional tables or one 3-dimensional table.
  • The tables can be in a wide range of sizes.
  • Cube files are trivial to write and read.
  • All values are human-readable as they are in decimal form, and can be of high precision.
  • The input domain and output range are not limited to the range 0.0 to 1.0.

According to the specifications, a CUBE file can be a One-Dimensional Cube file or a Three-Dimensional Cube file. From the example above you can see the file is a Three-Dimensional file with the required line “LUT_3D_SIZE“. But in a One-Dimensional file, the required line is “LUT_1D_SIZE“.

cat Demo.cube
TITLE "Demo"
LUT_1D_SIZE 3
DOMAIN_MIN 0 0 0
DOMAIN_MAX 1 2 3
0 0 0
# Comments can go anywhere
0.5 1 1.5
1 1 1

Each CUBE file has one or the other and should be an easy string to look for. It is in a variable position as there can be comments before the required line and also may have a TITLE line. The TITLE and DOMAIN lines are common to every file but not required.

Now, the CUBE format is a bit different depending on the source. They all seem to have the same header, but different elements. It seems the IRIDAS Cube format is the most interoperable. The Truelight Cube format generally has the CUB extension, and the Cinespace Cube has the CSP extension, which will look at next/ You can read more about the differences on this format comparison table. This LUTCalc web site has many different types of Cube’s it can output, so there are some differences.

The other file format available in the export is a CSP. The CSP is also a plain text file, often called a cineSpace LUT file. This format come from the cineSpace software, a color management software for the film and television industry.

cat LUTS-s01.csp 
CSPLUTV100
3D

BEGIN METADATA
#Created by: Adobe Photoshop Export Color Lookup Plugin
TITLE "LUTS"
END METADATA

2
0.0 1.0
0.0 1.0
2
0.0 1.0
0.0 1.0
2
0.0 1.0
0.0 1.0

32 32 32
0.000000 0.000000 0.000000

The CSP File Format specifications outlines header and the other two sections.:

The cineSpace LUT format contains three main sections.
Header
This section contains the LUT identifier and the LUT type, 3D or 1D.
It is made up of the first two (2) valid lines in the file. See Notes below for the definition of a valid line.

Examples
• (3D LUT) header:
CSPLUTV100
3D
• (1D LUT) header:
CSPLUTV100
1D

So there is a pretty obvious header to work with in identification. “CSPLUTV100” can be used to identify both 1D and 3D CSP files.

The other format available to export from Photoshop is 3DL. They seem to be connected to the Assimilate Inc. company and software. A specification has been posted, and it looks like there is only ASCII and not much in the way of a header.

cat LUTS-s01.3dl 
#Created by: Adobe Photoshop Export Color Lookup Plugin
#Description: LUTS
0 33 66 99 132 165 198 231 264 297 330 363 396 429 462 495 528 561 594 627 660 693 726 759 792 825 858 891 924 957 990 1023

It does not appear there is any headers or static strings to use for identification. The specification calls the format, 3DL ASCII format and that “All lines starting with ‘#’ are treated as comments.” Because of this, I don’t think positive identification can happen at this time.

For now I am just proposing 2 new file formats to PRONOM, The CUBE format And the CSP Format. Click on my GitHub submission page to see the signatures and enjoy some samples!

CD Architect

Receiving electronic media from an outside source can be an adventure. Often times you find yourself sorting the valuable files and separating them from the chaff. There can be hidden files, cache files, application files, drivers, and everything in between. Determining what formats are important can sometimes be difficult, especially if you don’t know the file format of some of the files.

I was recently working on a collection of files which had been produced through some audio software. When working with audio, a WAVE file is what is usually kept as they contain the actual audio data. With these files they came with a couple other formats. One of those formats was a bunch of SFK peak files. These files are meant to be temporary as they are generated from the WAVE file to make opening of audio data faster. They are important, but can easily be regenerated. One could argue they have historical value, but also they don’t contain anything that can be used by itself, so alone they don’t have much value.

The other format found with the WAVE files have a CDP extension. These came up as unknown when using DROID. It is not a common extension so finding the name of the software which created the files wasn’t too hard. Let’s take a look at one of them.

hexdump -C tutor1.cdp | head
00000000 52 49 46 46 79 03 00 00 53 46 50 4a 66 6d 74 20 |RIFFy...SFPJfmt |
00000010 18 00 00 00 00 00 01 00 02 00 00 00 10 00 00 00 |................|
00000020 44 ac 00 00 03 00 00 00 01 00 00 00 4c 49 53 54 |D...........LIST|
00000030 88 00 00 00 66 6c 73 74 66 69 6c 65 23 00 00 00 |....flstfile#...|
00000040 44 3a 5c 53 6f 75 6e 64 73 5c 4e 65 77 20 54 75 |D:\Sounds\New Tu|
00000050 74 6f 72 20 66 69 6c 65 73 5c 53 6f 6e 67 33 2e |tor files\Song3.|
00000060 77 61 76 00 66 69 6c 65 23 00 00 00 44 3a 5c 53 |wav.file#...D:\S|
00000070 6f 75 6e 64 73 5c 4e 65 77 20 54 75 74 6f 72 20 |ounds\New Tutor |
00000080 66 69 6c 65 73 5c 53 6f 6e 67 32 2e 77 61 76 00 |files\Song2.wav.|
00000090 66 69 6c 65 23 00 00 00 44 3a 5c 53 6f 75 6e 64 |file#...D:\Sound|

Huh, this is a RIFF file. RIFF is most commonly used as the container used for WAVE and AVI files. You can read more about the RIFF format on a previous post. The RIFF container format can be used for all sorts of things. Looking at the internals we can see a few unique list chunk’s.

Lots of references to other files, specifically WAVE files. But not a lot of actual data. That is because this format turns out to be just a project format for some software called “CD Architect“. Sonic Foundry was an audio software developer for a few years before they sold their catalog to Sony in 2003. In looking at the manual for CD Architect version 5.2, it explains the CDP Project format.

CD Architect software handles the organization of your CD using a small project file (CDP) that saves information about source file locations, edits, cuts, and insertion points. This project file is not a multimedia file, but is instead used to create the CD when editing is finished.

Looking at another CDP file from the collection, I noticed something different.

hexdump -C CDArch50a-s01.cdp | head
00000000 72 69 66 66 2e 91 cf 11 a5 d6 28 db 04 c1 00 00 |riff......(.....|
00000010 20 0a 00 00 00 00 00 00 84 38 15 b3 da 08 85 44 | ........8.....D|
00000020 b2 2a 5b 70 a1 32 15 ff 5a 2d 8f b2 0f 23 d2 11 |.*[p.2..Z-...#..|
00000030 86 af 00 c0 4f 8e db 8a 00 02 00 00 00 00 00 00 |....O...........|
00000040 78 00 00 00 00 00 04 00 11 00 00 00 44 ac 00 00 |x...........D...|
00000050 00 00 00 00 00 c0 52 40 00 00 00 00 00 00 5e 40 |......R@......^@|
00000060 00 00 00 00 00 00 00 00 04 00 04 00 40 00 00 00 |............@...|
00000070 00 00 00 00 00 00 00 00 00 00 00 00 7c 00 00 00 |............|...|
00000080 50 00 00 00 a0 00 00 00 00 00 00 00 00 00 00 00 |P...............|
00000090 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 |................|

That’s odd, the RIFF format is always uppercase ASCII, this is lowercase. Also the important RIFF form, which was “SFPJ” in the other sample, is missing. This is not a valid RIFF format.

But further down in the file I can see the same list chunks. Did they take RIFF format and make a proprietary version of their own? I think they may have. It seems the first example was from CD Architect version 4 and these other files are from CD Architect version 5. That complicates things. Sony stopped developing CD Architect after version 5.2d and maintained it for a few years before selling many of their titles to MAGIX Software. As far as I know there was never any new versions released. The software was very popular, as it had some really nice audio mastering features and was easy to use. Many were upset when the software was abandoned.

Creating a signature for both version 4 and version 5 CDP files will be pretty straightforward. I feel knowing what you have in a collection you are processing is the first step in making informed decisions. Wether or not you keep the project files are up for debate. Some may only want the final audio created from a CD Architect project, while others may want to see the way the audio was put together and mixed. Either way, the more you know…..

One more thing. CD Architect would default to saving a CDP project file, but could also save a “CD Image file”. This process actually would save the project to a full WAVE file with some extras baked in.

An image file is essentially a wave file with volume, crossfades, effects, mixes, and track information embedded. Burning an image file will reduce the risk of buffer underruns (especially if you have a complex project or are using a slow computer) since no audio processing is required. 

Interesting, normally when working with track information in a single WAVE file you would need a companion CUE Sheet in order to reference the track layout of the Audio CD. So I am curious how they do all of this. Lets take a look at a “CD Image”.

mediainfo CDArch52d-s02.wav
General
Complete name : CDArch52d-s02.wav
Format : Wave
Format settings : PcmWaveformat
File size : 5.05 MiB
Duration : 30 s 0 ms
Overall bit rate mode : Constant
Overall bit rate : 1 411 kb/s
Conformance errors : 2
RIFF : Yes
General compliance : File size 5292434 is less than expected size 5292823 (offset 0x8)
WAVE : Yes
General compliance : Element size 5292811 is more than maximal permitted size 5292422 (offset 0xC)

Audio
Format : PCM
Format settings : Little / Signed
Codec ID : 1
Duration : 30 s 0 ms
Bit rate mode : Constant
Bit rate : 1 411.2 kb/s
Channel(s) : 2 channels
Sampling rate : 44.1 kHz
Bit depth : 16 bits
Stream size : 5.05 MiB (100%)

Already seeing some issues with the format, but all the important bits are there. JHOVE doesn’t like them much either.

JhoveView (Rel. 1.32.0, 2024-09-12)
Date: 2024-12-11 16:01:08 MST
RepresentationInformation: CDArch52d-s02.wav
ReportingModule: WAVE-hul, Rel. 1.8.3 (2024-03-05)
LastModified: 2024-12-11 15:58:02 MST
Size: 5292434
Format: WAVE
Status: Not well-formed
SignatureMatches:
WAVE-hul
InfoMessage: Ignored unrecognized list type: "pqls"
ID: WAVE-HUL-15
Offset: 5292044
ErrorMessage: Unexpected end of file: Bytes missing = 389
ID: WAVE-HUL-3
Offset: 5292434
MIMEtype: audio/vnd.wave; codec=1
Profile: PCMWAVEFORMAT

JHOVE is giving me two issues. The major error is the file appears truncated according to both MediaInfo and JHOVE. The InfoMessage which is less of an issue but more of a heads up that the WAVE file has an extra LIST type. “PQLS”, which was also in the CPD RIFF file we looked at earlier. So it seems by making a “CD Image” of a project embeds the project chunk data into the WAVE container. Identification is not an issue as these WAVE’s follow the standard pattern and therefore identify correctly, but one might want to be aware through further characterization these WAVE’s have some not so obvious extra data.

My attempts to find any samples from version 3 of CD Architect have failed. Until then, my proposal is to add version 4 & 5 to PRONOM with the signature on my Github page. There you will find a few samples as well.

Daisy

A single file can often be self contained, having all that is needed to render itself with the correct software, but more and more often files need other files to function properly. Sometimes these groups of dependent files are within a container, such as a DOCX or ePub, but can also be found all sitting nicely in a folder. I say nicely, partly because the structure works, that is until they are treated as individual files and renamed or moved around breaking that interdependence on each other.

In the case of many Apple bundle files, they appear to be a single file when using on the MacOS, but as a folder on Windows or Linux. This can be very confusing. In other cases such as the DAISY Digital Talking Book format, it is simply a folder or disc with a few or many files within.

Current tools used to identify file formats, such as DROID, look at individual files, not groups of files to determine format. Each file within a folder may have a unique format, but when grouped with other specific formats they become something more. We will have to work on enhancing current tools if we want to avoid breaking these format types and losing their ability to render properly.

DAISY, or Digital Accessible Information System, is a type of Digital Book. The format was originally conceived in 1988 as a method to create a talking book, designed for the purpose of giving those who are visually impaired the ability to listen to books. It wasn’t until 1996, the DAISY Consortium was created in order to take the technology to those who needed it. The original version of the the DAISY format in 1994 was proprietary, but once they formed the consortium, they decided to adopt open standards for the format and in 1998, the DAISY 2.0 standard was released. You can read more on the Library of Congress Format Description page.

Lets take a look at a folder containing a DAISY 2.0 book.

ls -la "DAISY 2.02 export"
total 536
drwx------ 1 tyler staff 16384 Sep 25 22:06 .
drwx------ 1 tyler staff 16384 Sep 25 22:06 ..
-rwx------@ 1 tyler staff 1090 Sep 25 22:05 0002.smil
-rwx------ 1 tyler staff 228413 Sep 25 22:05 aud0001.mp3
-rwx------@ 1 tyler staff 672 Sep 25 22:05 master.smil
-rwx------ 1 tyler staff 1703 Sep 25 22:05 ncc.html

We can see three different formats in this folder. The obvious well known MP3 files and an HTML file. We also see two files with the extension SMIL.

“Synchronized Multimedia Integration Language” or SMIL is a W3C XML standard used to describe multimedia presentations. It is used in the DAISY DTB as well as other applications, but we will focus on DAISY, and it is in its third version. A SMIL file has this structure:

<?xml version="1.0"?>
<!DOCTYPE smil PUBLIC "-//W3C//DTD SMIL 1.0//EN" "http://www.w3.org/TR/REC-smil/SMIL10.dtd">
<smil>
<head>
<meta name="dc:title" content="Obi Project" />
<meta name="dc:identifier" content="589c550e-303b-4c0d-9921-ae76d782fd53" />
<meta name="ncc:generator" content="Obi v5.0.0.0 with toolkit: UrakawaSDK.core v2.0.0.0 (http://urakawa.sf.net/obi)" />
<meta name="dc:format" content="Daisy 2.02" />
<meta name="ncc:timeInThisSmil" content="00:00:28" />
<layout>
<region id="textView" />
</layout>
</head>
<body>
<ref title="Testing" src="0002.smil" id="ms_0002" />
</body>
</smil>

A standard XML file with a link to a SMIL DTD and a root tag of <smil>. This format is recognized by PRONOM as fmt/205, although is often identified as a standard XML file. It seems the signature was created with a small offset which works with some SMIL files, but the gap between the end of the XML declaration and the start of the <smil> tag is only 20-86 bytes, not enough to allow for different character sets and full DTD URL’s. We will have to increase this gap in order to get all the SMIL files identified correctly.

With this update all the files in a DAISY 2.0 files should be identified individually, but as a set of files they make up the DAISY 2.0 format. This format requires the ncc.html file be present at the root of the folder or CD, so this file will aid in the manual identification of this format.

DAISY 3 was released in 2002 and standardized using the ANSI/NISO Z39.86 2002 name. It has been revised a couple times with the current revision being 2012. This update adds more functionality to the format with many new optional and required formats/files included in the folder. Here is a simple example:

ls -la "DAISY3 Export"
total 784
drwx------ 1 tyler staff 16384 Sep 25 22:06 .
drwx------ 1 tyler staff 16384 Sep 25 22:06 ..
-rwx------@ 1 tyler staff 979 Sep 25 22:05 0001.smil
-rwx------ 1 tyler staff 228413 Sep 25 22:05 aud0001.mp3
-rwx------ 1 tyler staff 1014 Sep 25 22:05 navigation.ncx
-rwx------ 1 tyler staff 1881 Sep 25 22:05 package.opf
-rwx------ 1 tyler staff 7838 Nov 2 2020 tpbnarrator.res
-rwx------ 1 tyler staff 117656 Nov 2 2020 tpbnarrator_res.mp3

The SMIL format is still included, along with MP3’s, but we have some addition formats. The NCX or “Navigation Control File”, the OPF or “Package file”, and the RES or “Resource file” are a few of them. The NCX file is the first file accessed as it lays out the navigation for the whole DTB. It is also XML:

cat DAISY3 Export/navigation.ncx 
<?xml version="1.0" encoding="utf-8"?>
<!DOCTYPE ncx PUBLIC "-//NISO//DTD ncx 2005-1//EN" "http://www.daisy.org/z3986/2005/ncx-2005-1.dtd">
<ncx
version="2005-1"
xml:lang="en-US" xmlns="http://www.daisy.org/z3986/2005/ncx/">

This file is only recognized by DROID as a standard XML file. It probably should have unique identification like SMIL and with a root tag of <ncx>, that should be fairly easy to add.

The Package file with the extension OPF, is actually a format used by the openebook group, not to be confused by a format used by the Open Preservation Foundation 🤣. The Open Packaging Format is used and a DTB conforming to this standard must include exactly one Package File which must be a valid XML 1.0 document conforming to the OEBF Publication Structure 1.2 package.

cat DAISY3 Export/package.opf   
<?xml version="1.0" encoding="utf-8"?>
<!DOCTYPE package PUBLIC "+//ISBN 0-9673008-1-9//DTD OEB 1.2 Package//EN" "http://openebook.org/dtds/oeb-1.2/oebpkg12.dtd">
<package
unique-identifier="uid" xmlns="http://openebook.org/namespaces/oeb-package/1.0/">
<metadata>
<dc-metadata xmlns:dc="http://purl.org/dc/elements/1.1/" xmlns:oebpackage="http://openebook.org/namespaces/oeb-package/1.0/">
<dc:Identifier
id="uid">589c550e-303b-4c0d-9921-ae76d782fd53</dc:Identifier>
<dc:Format>ANSI/NISO Z39.86-2005</dc:Format>
<dc:Title>Obi Project</dc:Title>
<dc:Publisher>N/A</dc:Publisher>
<dc:Language>en-US</dc:Language>
<dc:Creator>Creator name</dc:Creator>
<dc:Date>2024-09-25</dc:Date>
</dc-metadata>

The OPF format is also unknown to PRONOM and they identify as standard XML files as well. The root tag of “<package>” could be used elsewhere so the signature may need to reference the OEB package information.

The RES Resource file is also a standard XML and can be identified through its root tag of “<resources>” and resources DOCTYPE.

cat DAISY3 Export/tpbnarrator.res 
<?xml version='1.0' encoding='UTF-8'?>
<!DOCTYPE resources PUBLIC "-//NISO//DTD resource 2005-1//EN" "http://www.daisy.org/z3986/2005/resource-2005-1.dtd" []>
<resources xmlns="http://www.daisy.org/z3986/2005/resource/" version="2005-1">

<!-- SKIPPABLE NCX -->

<scope nsuri="http://www.daisy.org/z3986/2005/ncx/">
<nodeSet id="ns001" select="//smilCustomTest[@bookStruct='LINE_NUMBER']">
<resource xml:lang="en" id="r001">
<text>Row</text>
<audio src="tpbnarrator_res.mp3" clipBegin="0:00:02.379" clipEnd="0:00:03.416" />
</resource>
</nodeSet>

Now, adding these DAISY 3.0 formats will greatly increase the identification of this complex format. But we run into a problem with some of the software out there which generates these DAISY files, some of them include files not required by the format, but are included to be used by the different software. This can include some CSS files for formatting, additional XML, XSL files, DTD’s, and for DAISY files created by the PlexTalk software, additional project files.

ls -la MasterCD/AfterBuild 
total 7520
drwx------@ 1 tyler staff 16384 Sep 24 19:34 .
drwx------@ 1 tyler staff 16384 Sep 25 22:11 ..
-rwx------@ 1 tyler staff 6688 Sep 25 01:32 ImdPhrInfo.imph
-rwx------@ 1 tyler staff 3773 Sep 25 01:32 ImdTxtTabl.imtt
-rwx------@ 1 tyler staff 1276 Sep 25 01:32 Ncc.imdn
-rwx------@ 1 tyler staff 3716618 Sep 25 01:32 a000001.mp3
-rwx------@ 1 tyler staff 4352 Sep 25 01:32 ncc.html
-rwx------@ 1 tyler staff 1015 Sep 25 01:32 ptk000001.smil
-rwx------@ 1 tyler staff 938 Sep 25 01:32 ptk000002.smil

The ncc.html file is here, indicating a DAISY 2.0 format, along with an MP3 and SMIL files, but including some additional formats.

In addition, when creating a project, four files with the extensions Ncc.imdn, ImdPhrInfo.imph, ImdTxtTabl.imtt, and METADATA.ini are automatically created. These files are called “Plextalk project files.” They store table of contents information, etc. (Plextalk project files generated by older versions of this product do not have METADATA.ini.)

http://www.plextalk.com/jp/dw_data/PRSStd/PLEX_RS_UM.html

These four files may not be crucial to the playing of the Daisy format, but they are important to the PlexTalk software.

hexdump -C ImdPhrInfo.imph | head
00000000 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 |................|
*
00000020 ff ff ff ff ff ff ff ff 00 00 00 00 00 00 00 00 |................|
00000030 00 00 00 00 00 00 00 00 f0 a3 0d 00 00 00 00 00 |................|
00000040 a3 06 00 00 a4 06 00 00 00 00 00 00 53 00 00 00 |............S...|
00000050 ff ff ff ff 01 00 00 00 03 00 00 00 00 00 00 00 |................|
00000060 00 00 00 00 00 00 00 00 c5 11 00 00 20 1a 00 00 |............ ...|
00000070 e5 2b 00 00 00 00 00 00 63 00 00 00 ff ff ff ff |.+......c.......|
00000080 02 00 00 00 04 00 00 00 00 00 00 00 00 00 00 00 |................|
00000090 00 00 00 00 e5 2b 00 00 d6 0b 00 00 bb 37 00 00 |.....+.......7..|

hexdump -C ImdTxtTabl.imtt | head
00000000 17 00 00 00 32 30 30 34 2f 30 35 2f 33 31 2f 31 |....2004/05/31/1|
00000010 36 3a 36 3a 34 37 2e 30 30 30 00 03 00 00 00 65 |6:6:47.000.....e|
00000020 6e 00 0b 00 00 00 69 73 6f 2d 38 38 35 39 2d 31 |n.....iso-8859-1|
00000030 00 0d 00 00 00 5a 3a 2f 42 6f 6f 6b 44 69 72 34 |.....Z:/BookDir4|
00000040 2f 00 0d 00 00 00 5a 3a 2f 42 6f 6f 6b 44 69 72 |/.....Z:/BookDir|
00000050 34 2f 00 0c 00 00 00 61 30 30 30 30 30 31 2e 6d |4/.....a000001.m|
00000060 70 33 00 0c 00 00 00 61 30 30 30 30 30 31 2e 6d |p3.....a000001.m|
*
00000980 70 33 00 08 00 00 00 48 65 61 64 69 6e 67 00 01 |p3.....Heading..|
00000990 00 00 00 00 08 00 00 00 48 65 61 64 69 6e 67 00 |........Heading.|

hexdump -C Ncc.imdn | head
00000000 01 ff 00 ff c4 00 00 00 3c 00 00 00 2c 00 00 00 |........<...,...|
00000010 14 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 |................|
00000020 00 00 00 00 49 6d 64 54 78 74 54 61 62 6c 2e 69 |....ImdTxtTabl.i|
00000030 6d 74 74 00 00 00 00 00 00 00 00 00 00 00 00 00 |mtt.............|
00000040 00 00 00 00 49 6d 64 50 68 72 49 6e 66 6f 2e 69 |....ImdPhrInfo.i|
00000050 6d 70 68 00 00 00 00 00 00 00 00 00 00 00 00 00 |mph.............|
00000060 00 00 00 00 04 00 00 00 00 fa 00 00 44 ac 00 00 |............D...|
00000070 01 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 |................|
00000080 00 00 00 00 01 00 00 00 08 00 00 00 12 00 00 00 |................|
00000090 03 00 00 00 00 00 00 00 01 00 00 00 ff ff ff ff |................|

I don’t have a METADATA.ini file to research, but I will be honest, these PlexTalk files will be hard to identify from their contents.

Looking at the IMPH file, there isn’t a lot of bytes which might indicate a format magic bytes. But I do see some patterns. The first 40 bytes all seem to be the same.

00000000 00000000 00000000 00000000 00000000 00000000 00000000 00000000 FFFFFFFF FFFFFFFF

But making a signature from only 00 and FF might clash with other formats. It does appear that the 4 bytes FFFFFFFF occur every 40 bytes. This precision might be good enough if we repeat it a couple times.

The IMTT file is different. It appears to have information on the name, character set and all the files in the Daisy package. The first 4 bytes in my 14 samples either start with 17000000 or 18000000. Not knowing what the 17 or 18 refers to, I am hesitant to use it for identification. In between some of the data there is some consistent bytes, but at different offsets.


hexdump -C ImdTxtTabl.imtt | head
00000000 18 00 00 00 54 69 74 6c 65 00 35 39 2d 31 00 31 |....Title.59-1.1|
00000010 35 3a 35 34 3a 35 39 2e 32 36 30 00 03 00 00 00 |5:54:59.260.....|
00000020 65 6e 00 0b 00 00 00 69 73 6f 2d 38 38 35 39 2d |en.....iso-8859-|
00000030 31 00 01 00 00 00 00 01 00 00 00 00 01 00 00 00 |1...............|
00000040 00 01 00 00 00 00 01 00 00 00 00 01 00 00 00 00 |................|
00000050 01 00 00 00 00 01 00 00 00 00 0c 00 00 00 4d 61 |..............Ma|
00000060 72 69 6f 6e 20 53 79 6d 65 00 28 00 00 00 4d 69 |rion Syme.(...Mi|
00000070 6e 75 74 65 73 20 6f 66 20 74 68 65 20 43 6f 6d |nutes of the Com|
00000080 6d 69 74 74 65 65 20 4d 65 65 74 69 6e 67 20 32 |mittee Meeting 2|
00000090 34 30 35 30 34 00 08 00 00 00 48 65 61 64 69 6e |40504.....Headin|

hexdump -C ImdTxtTabl.imtt | head
00000000 17 00 00 00 32 30 30 34 2f 30 35 2f 33 31 2f 31 |....2004/05/31/1|
00000010 36 3a 36 3a 34 37 2e 30 30 30 00 03 00 00 00 65 |6:6:47.000.....e|
00000020 6e 00 0b 00 00 00 69 73 6f 2d 38 38 35 39 2d 31 |n.....iso-8859-1|
00000030 00 0d 00 00 00 5a 3a 2f 42 6f 6f 6b 44 69 72 34 |.....Z:/BookDir4|
00000040 2f 00 0d 00 00 00 5a 3a 2f 42 6f 6f 6b 44 69 72 |/.....Z:/BookDir|
00000050 34 2f 00 0c 00 00 00 61 30 30 30 30 30 31 2e 6d |4/.....a000001.m|
00000060 70 33 00 0c 00 00 00 61 30 30 30 30 30 31 2e 6d |p3.....a000001.m|

Not sure what any of it means, but might be good enough for a signature.

Now the IMDN files might be a little easier:

hexdump -C Ncc.imdn | head
00000000 01 ff 00 ff d4 00 00 00 3c 00 00 00 2c 00 00 00 |........<...,...|
00000010 14 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 |................|
00000020 00 00 00 00 49 6d 64 54 78 74 54 61 62 6c 2e 69 |....ImdTxtTabl.i|
00000030 6d 74 74 00 00 00 00 00 00 00 00 00 00 00 00 00 |mtt.............|
00000040 00 00 00 00 49 6d 64 50 68 72 49 6e 66 6f 2e 69 |....ImdPhrInfo.i|
00000050 6d 70 68 00 00 00 00 00 00 00 00 00 00 00 00 00 |mph.............|
00000060 00 00 00 00 04 00 00 00 00 7d 00 00 22 56 00 00 |.........}.."V..|
00000070 01 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 |................|
00000080 00 00 00 00 01 00 00 00 28 00 00 00 28 00 00 00 |........(...(...|
00000090 00 00 00 00 00 00 00 00 28 00 00 00 ff ff ff ff |........(.......|

This format directly names the two other formats. Should be easy to look for the two file names in the header. The NCC html file in Daisy 2.0 and the NCX xml file in Daisy 3.0 are directory files so it makes sense this file would do the same.

Not sure if these signatures will hold up over time, but they are a start. It would be nice if all the files we are given to preserve would have convenient static magic bytes, but alas, many do not and we have to guess.

These Daisy formats illustrate a problem in preservation that doesn’t quite have a good solution. Each of these files are individually unique and can be identified, but as a whole they represent another unique format. Tying formats together to link their interdependence on each other will be no small task, but will be necessary not only to understanding the format, but to avoid separating the files, renaming, or rearranging breaking that interdependence.

I have added the update to SMIL and new signatures for the other formats to my GitHub repository. Feel free to test and change if you find additional samples or information.